Hopp til hovedinnhold

Model tests

New AI models, tested on real tasks

When the major providers release new models, we test them on three fixed production tasks: a 3D flight over NMBU, an analysis of the Norwegian Oil Fund and a promotional film. Every model gets the same starting point, so the results can be compared over time.

Other benchmarks Arena has measured all 6 models we have tested, and Epoch AI 5 of them. See what they say.

First: how

How we test

A model that writes good answers in a chat window is not necessarily good at finishing a whole piece of work. So we give the models larger tasks of the kind a teacher or student could actually commission, and look at what comes out.

What we add

Norwegian material and whole tasks

International benchmarks are useful, but they measure something other than what we test. With us, the task text, the material and the delivery are Norwegian, and it is the finished work that is assessed.

Norwegian material and whole tasks
WhatInternational benchmarks, typicallyOur tests
LanguageMostly English.A Norwegian task text and Norwegian material, and the model has to write in Norwegian Bokmål.
The taskBounded questions with an answer key, such as the multiple-choice questions in GPQA Diamond, or coding tasks from GitHub, as in SWE-bench Verified.A whole production task: a 3D experience, an interactive report or a film with slides.
The assessmentAutomatic against the answer key, or user votes: in Arena, users pick the better of two anonymous answers.A person opens and uses the delivery, recalculates the key figures and checks every point in the task.
The resultA score or a place in a ranking.Four scores, a separate score for honesty, and the actual time, number of steps and cost at the provider.

The material the models get

  • The NMBU campus in Ås: a topographic map from the Norwegian Mapping Authority (Kartverket), NMBU's park map and eleven photographs of Urbygningen, Tårnbygningen and Storplenen.
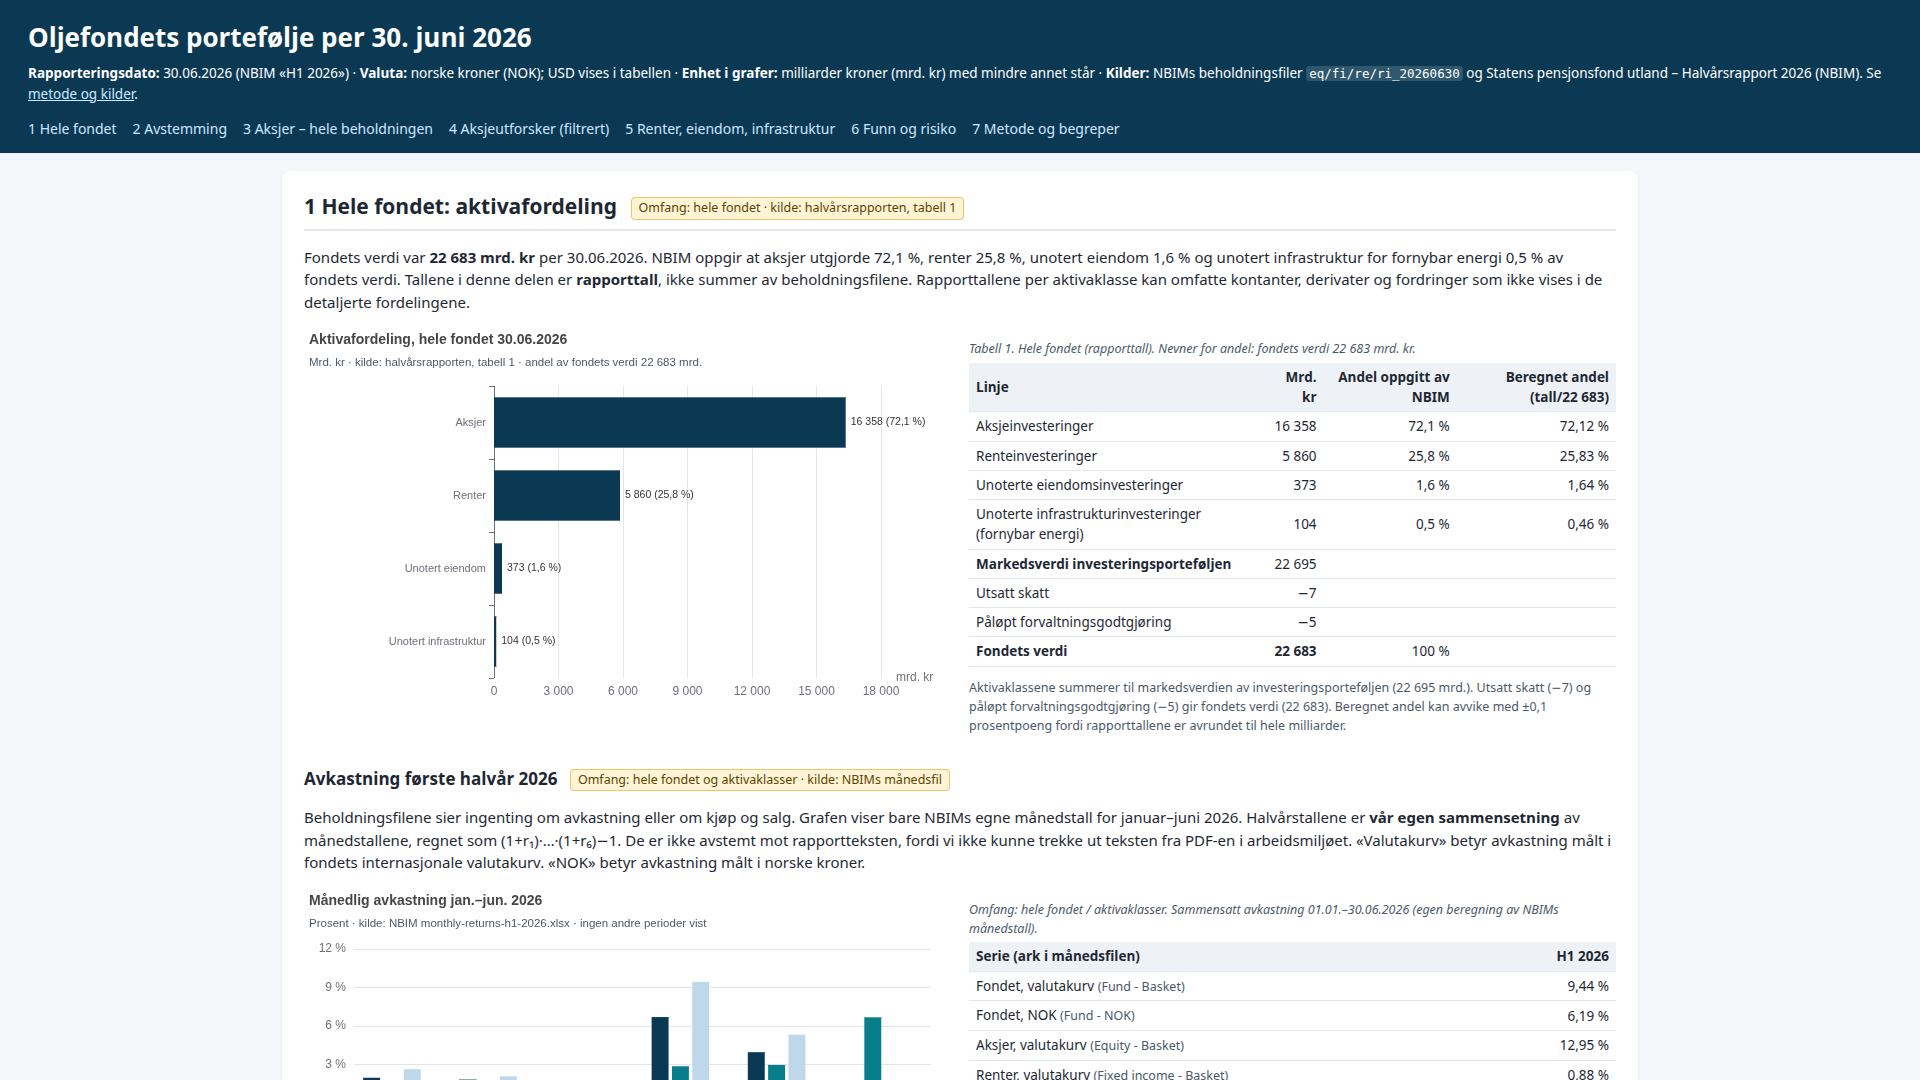
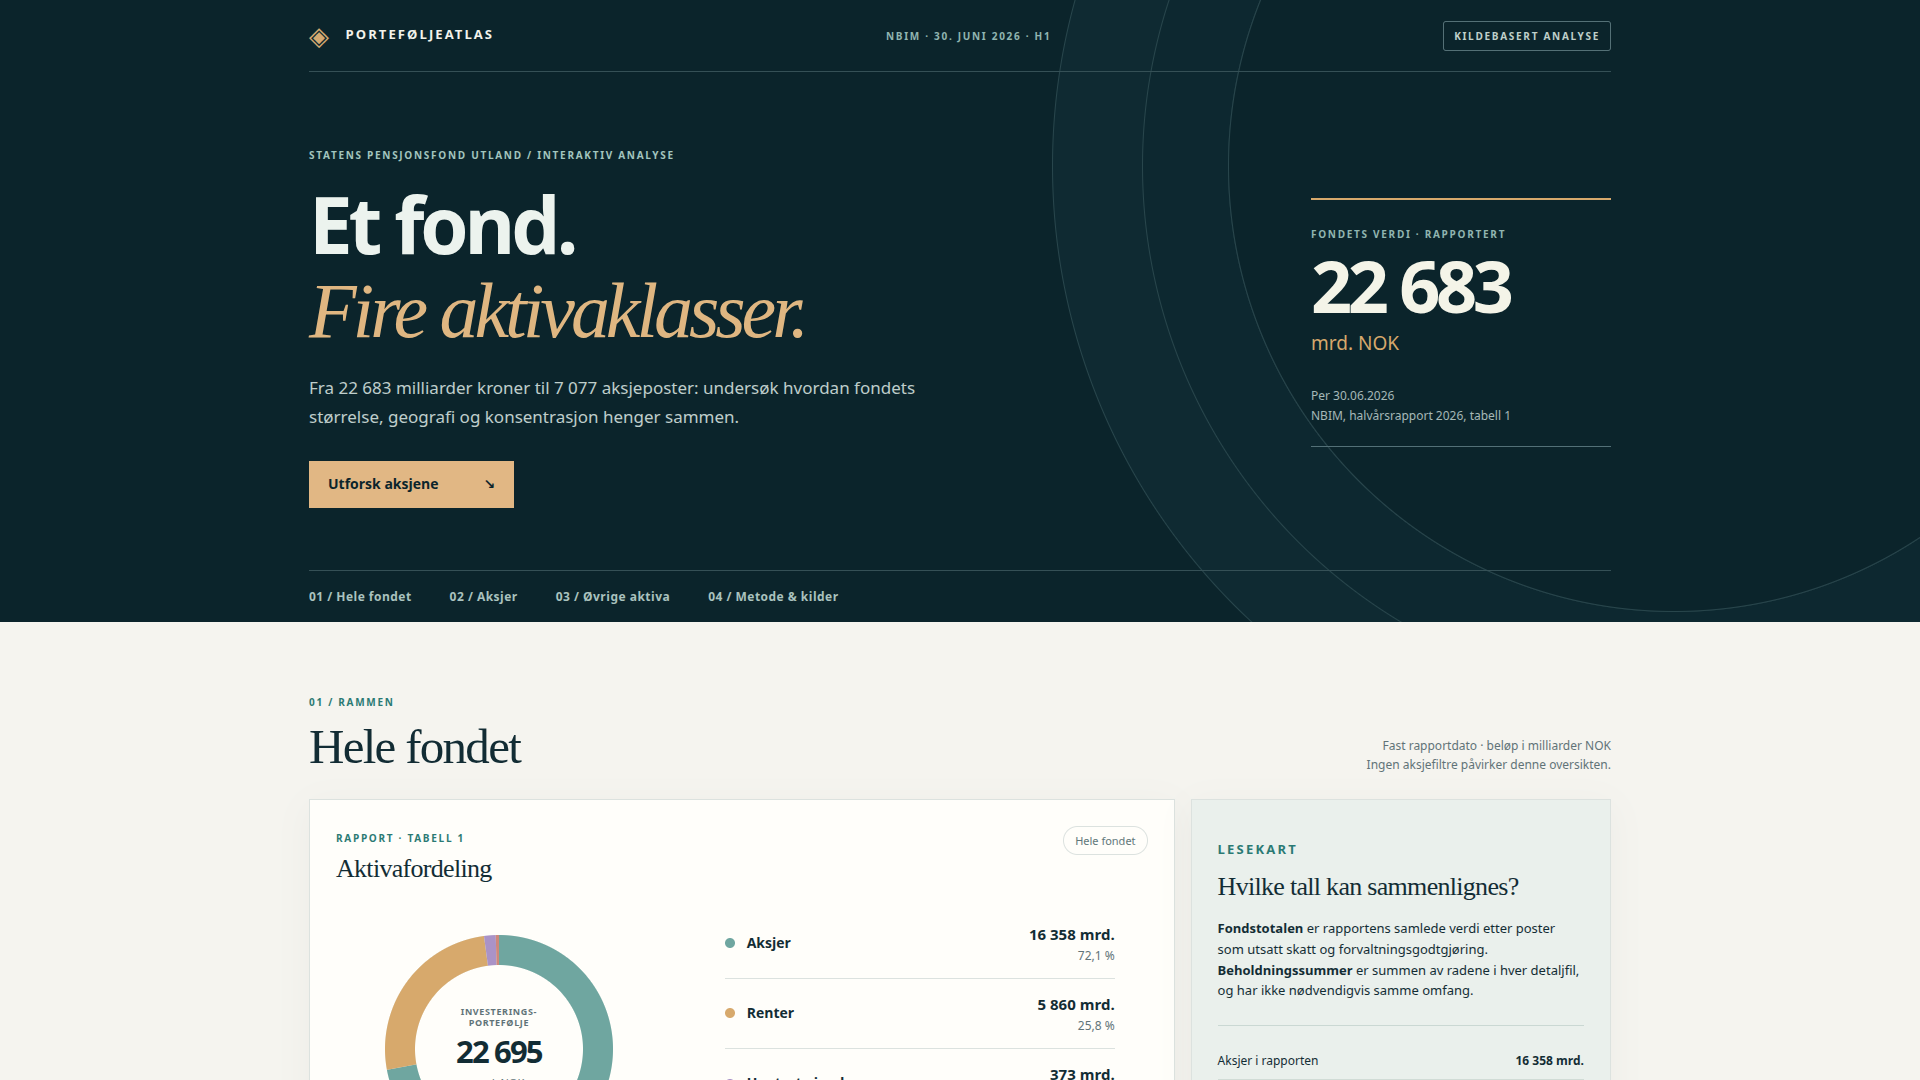
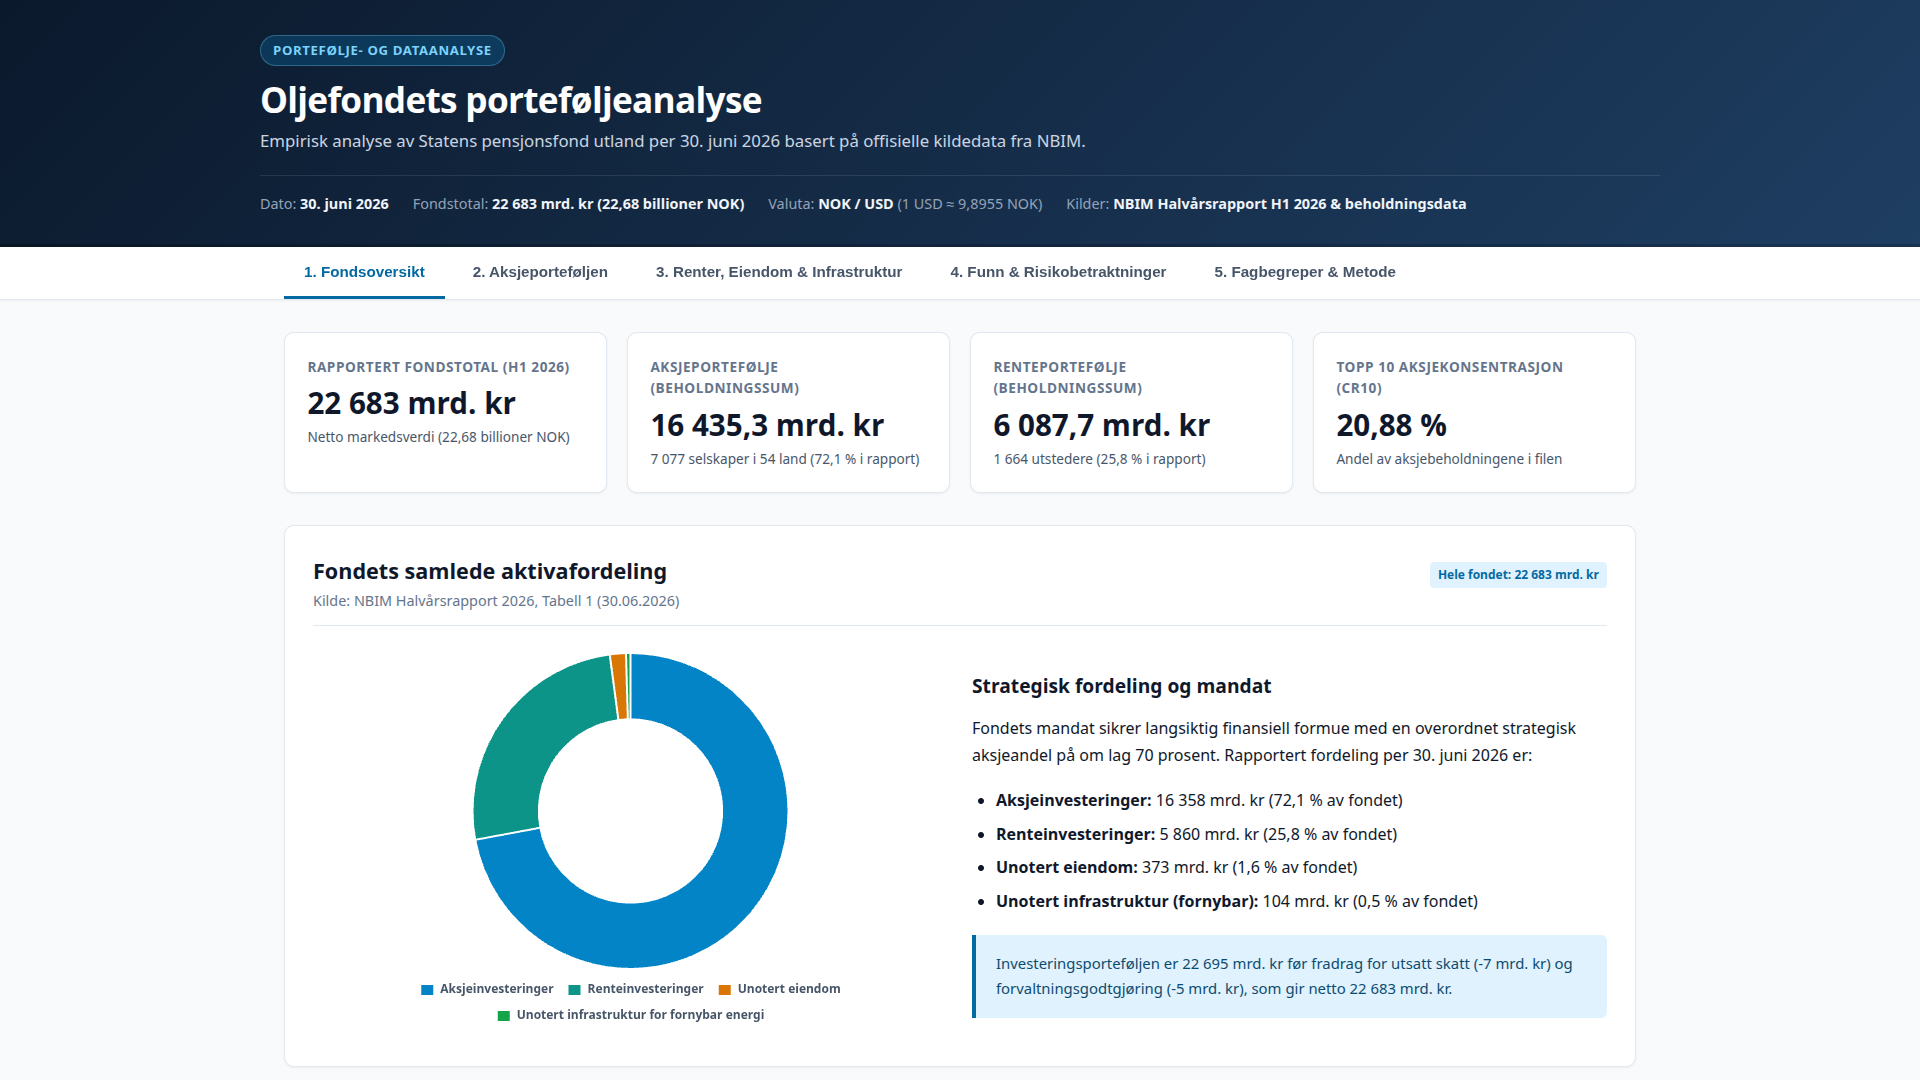
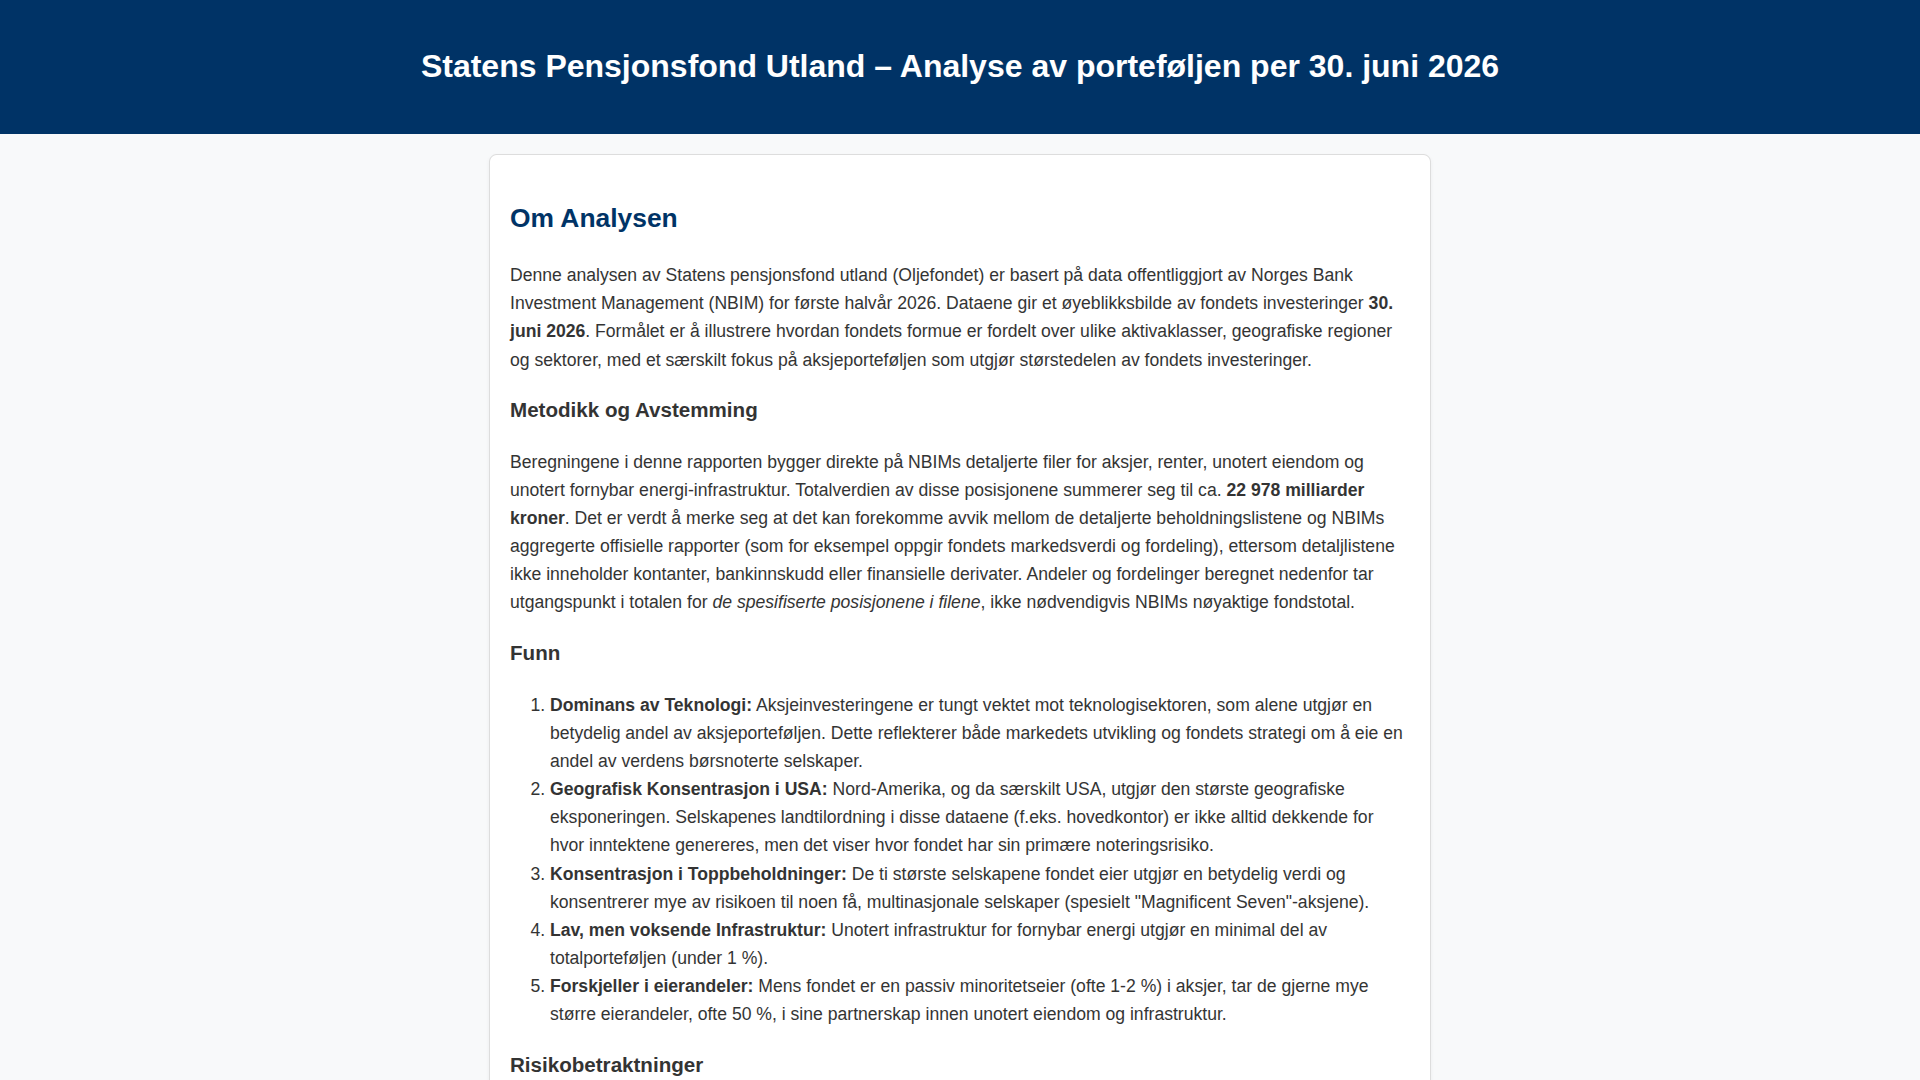
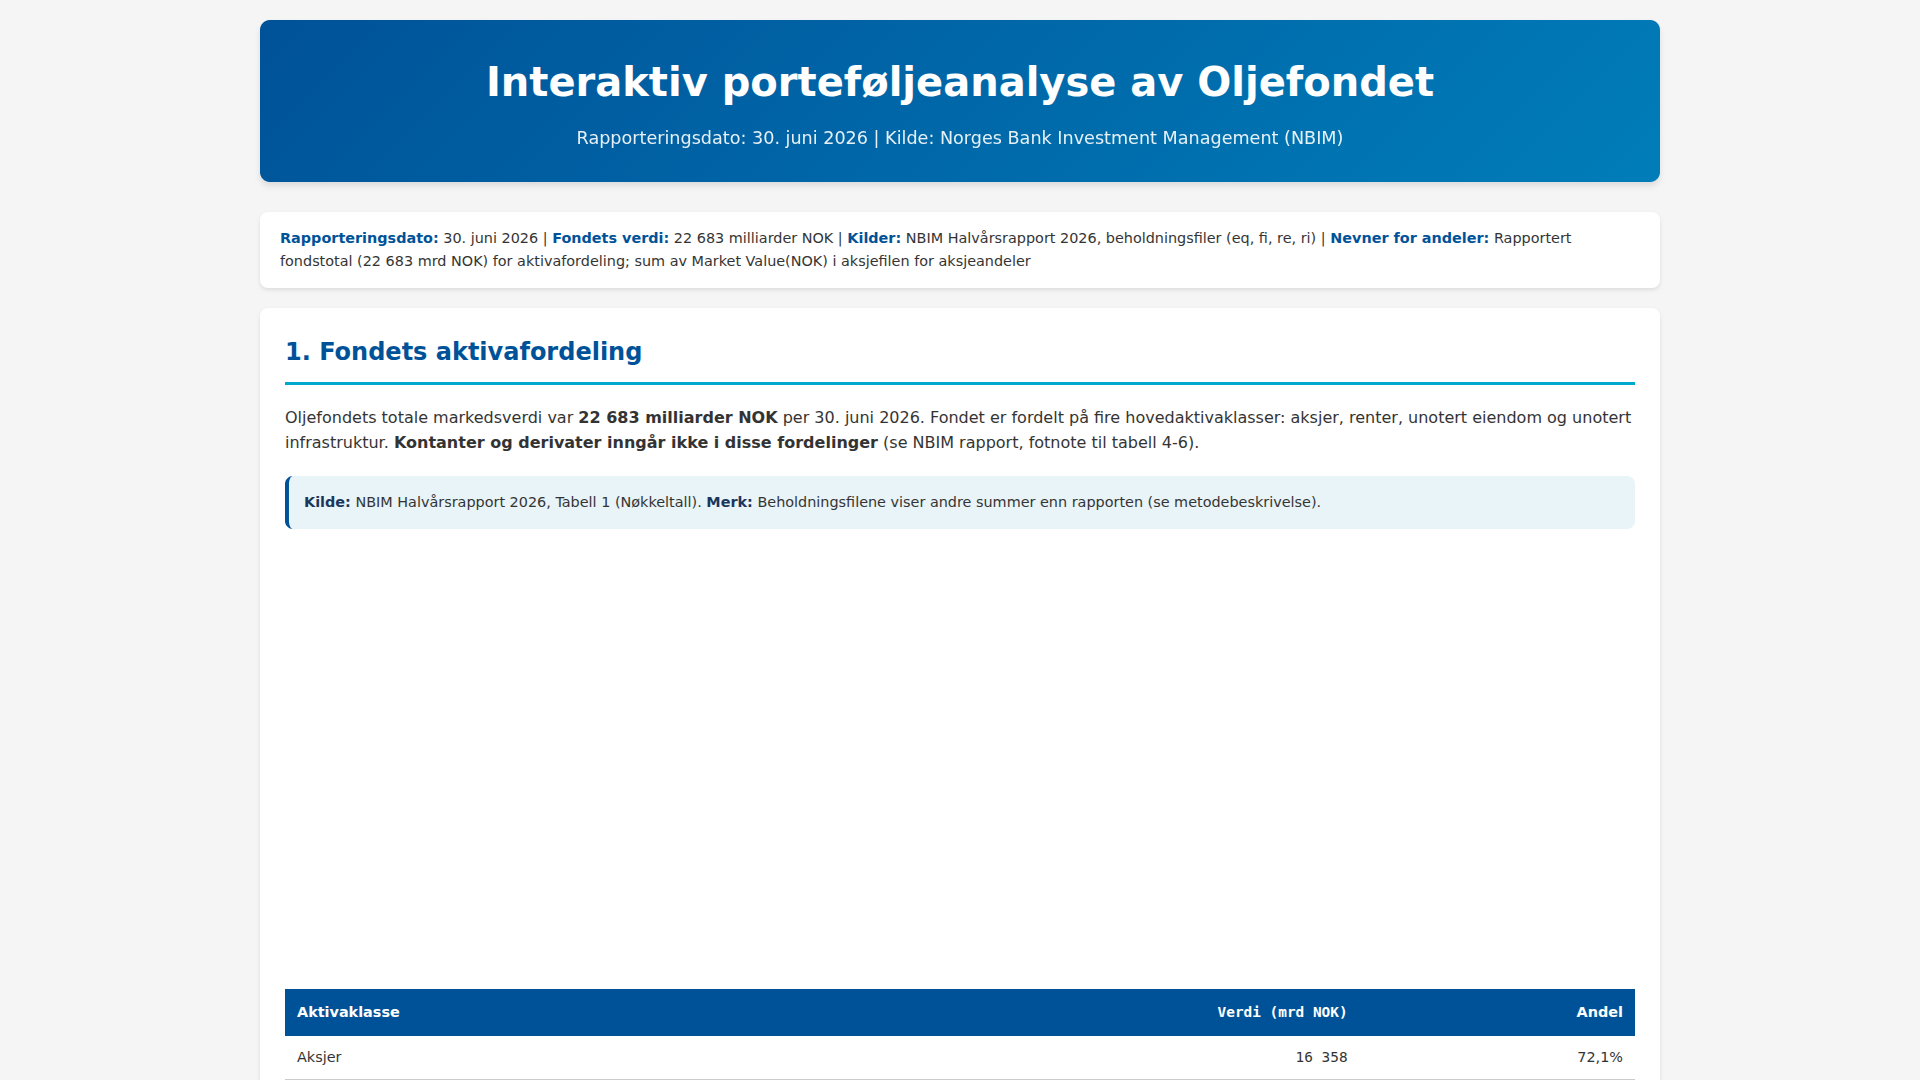
  • The Oil Fund: NBIM's own holdings files as at 30 June 2026, with all 7,077 listed companies, and the official Norwegian half-year report.
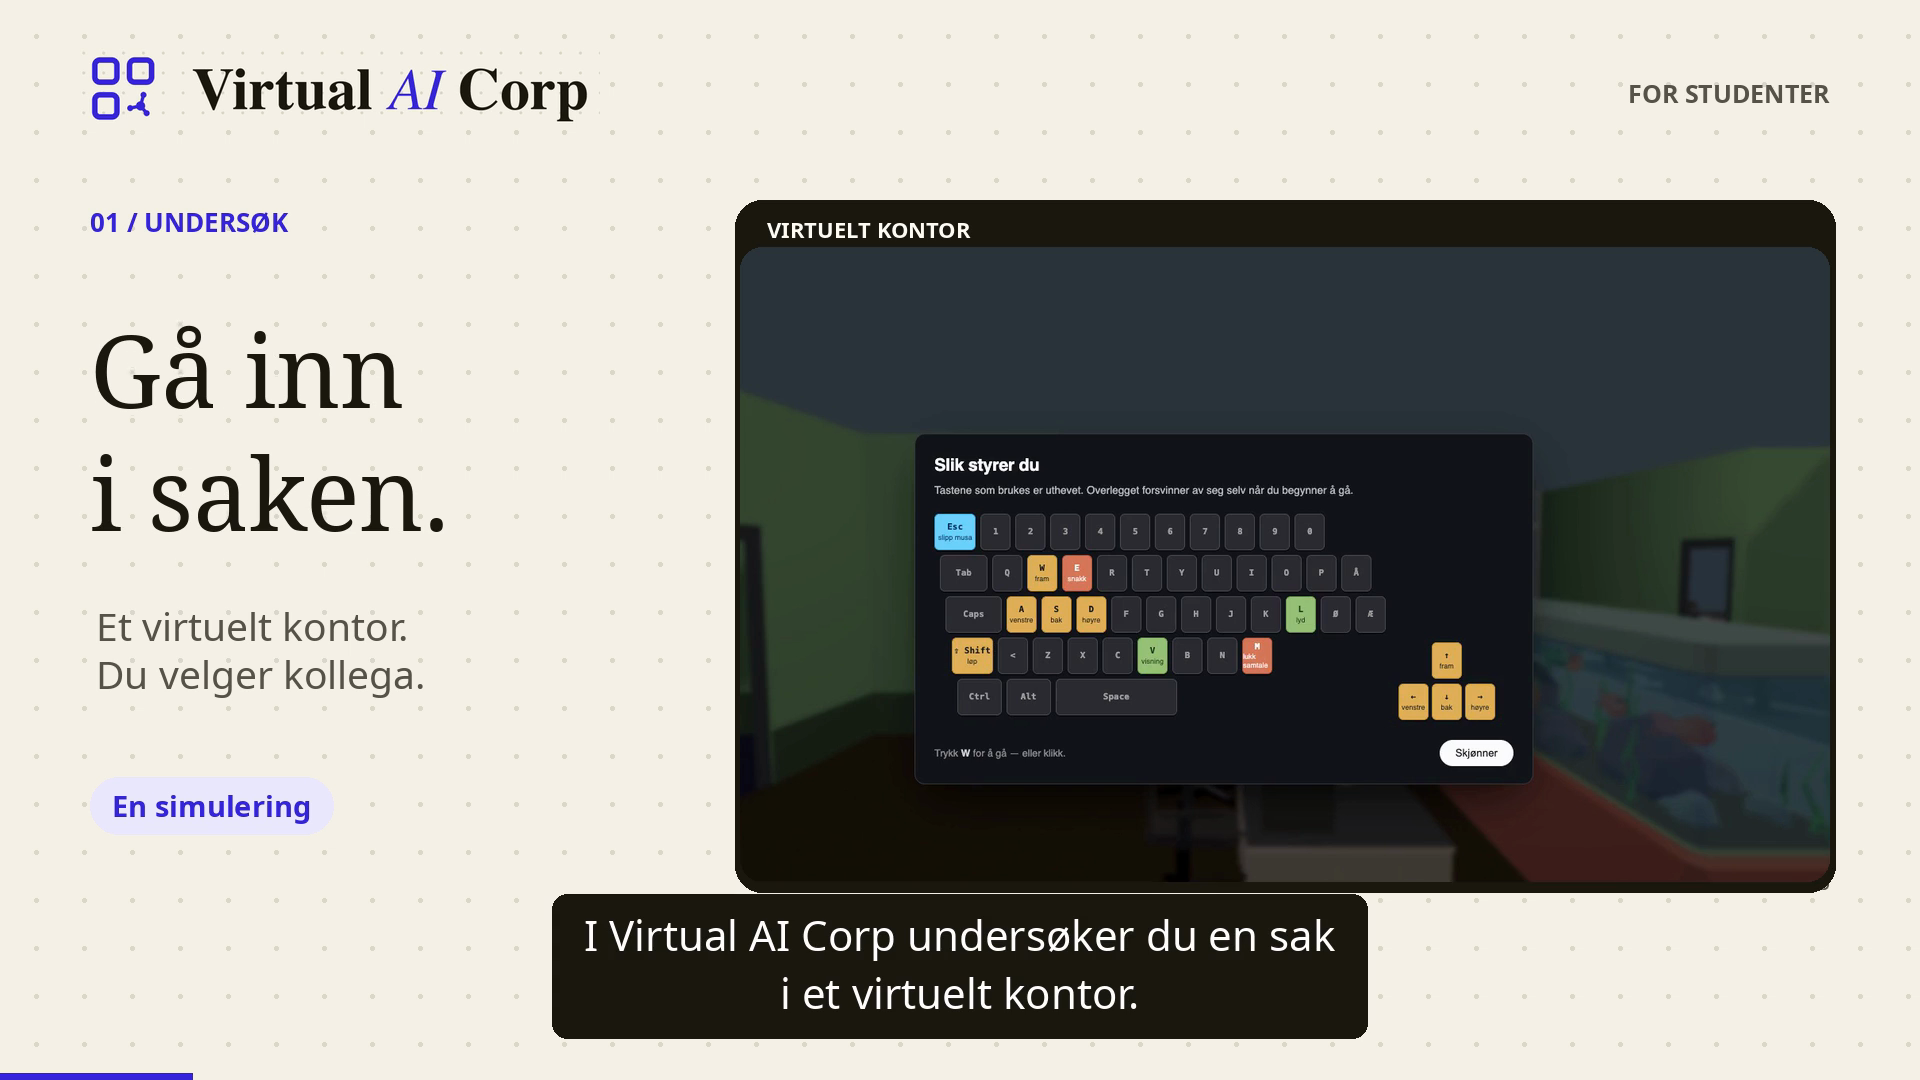
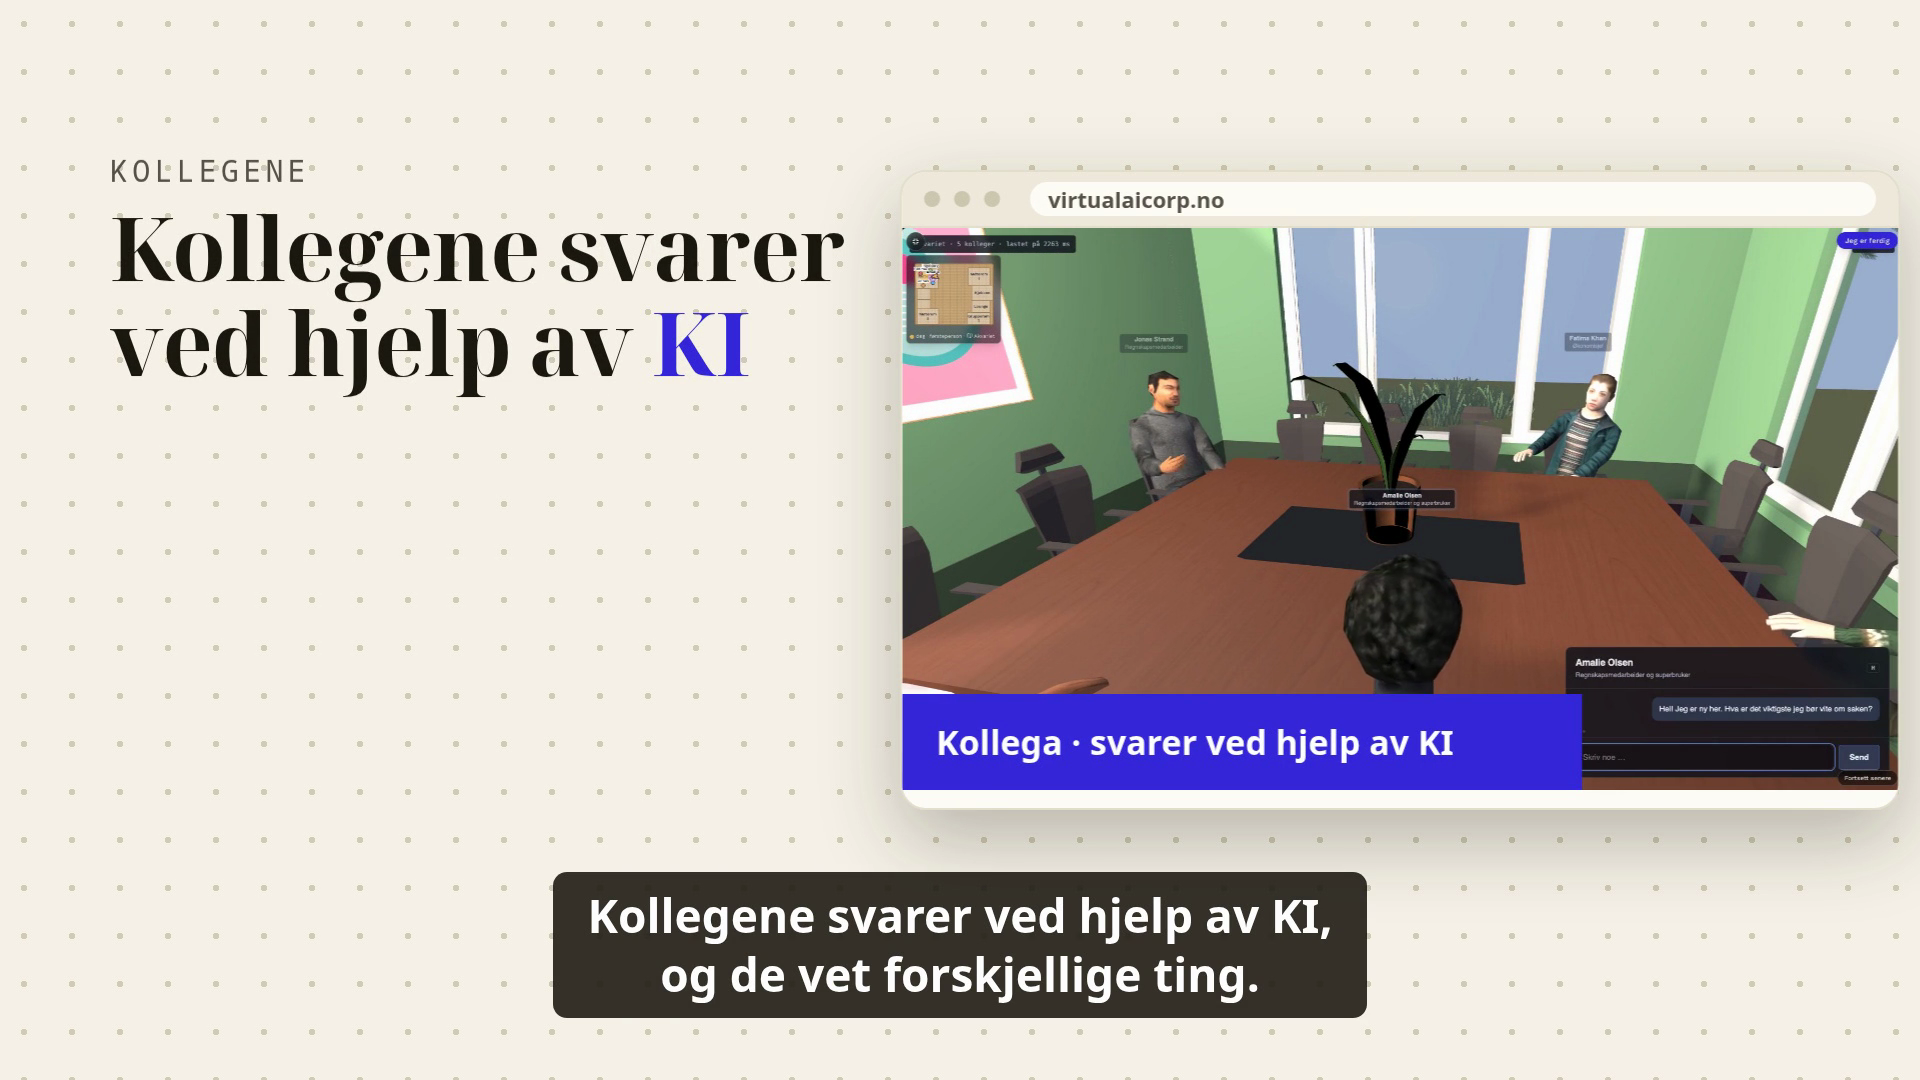
  • The promotional film: an approved Norwegian student brief with a source for every claim, the student video from our front page and screenshots of our own pages.
  • The film has to have a Norwegian voice-over with a fixed Norwegian voice, and Norwegian subtitles.
  1. The same task for everyone

    Every model gets the same task text, the same material and the same limits: 30 minutes and 200 steps per task.

  2. A closed working environment

    The model works in its own container with no network and no access to our systems. It can run code, take screenshots, render video and make presentations.

  3. No help along the way

    The run is automatic from start to finish. We log the time, the number of steps and the actual cost at the provider.

  4. Reviewed before publication

    We go through every delivery before it is published, and assess whether it works, follows the task, is of good quality and how much follow-up work it needs.

The tasks

Three fixed tasks

The tasks are the same in every round, so a new model can be compared with those tested before.

The assessment

How we score

We read the whole delivery, recalculate the key figures, open the result as a user would and check every point in the task. A fault is deducted only where it belongs most. Each model gets one attempt per task.

Four scores from 1 to 5. The average of them is the number you see in the comparison.

  1. Works

    Does the delivery start, and does it do what it promises? 5 means everything works without faults, 1 means it does not start.

  2. Follows the task

    Was everything that was ordered delivered within the limits? Invented figures, facts or sources give 2 at most.

  3. Quality

    Academic, visual and creative level. 5 means it could be shown to students as it is.

  4. Little follow-up work

    How much we would have to do before we could use it. 5 is nothing, 1 means it has to be redone.

Comparison

How the models did

In short

If you want the best result
Choose GPT-6.1 Sol, Claude Opus 5.5 or GPT-6 Sol. All scored 4.75 out of 5 on all three tasks, and all were honest about their own shortcomings (5 out of 5 on all three).
If you want the most for your money
GPT-6.1 Sol got the same score as Claude Opus 5.5 at USD 2.42 for all three tasks, compared with USD 5.39.
If you want a low price and speed
Gemini 3.1 Pro cost USD 1.53 and took 12 min 56 s for all three, but its average is 3.0. Expect a fair amount of follow-up work.
If data must be processed in the EU
Mistral Medium 3.5 is the only model in the test with processing in the EU. It scored 1.5 on the drone task and 2.25 on the Oil Fund task. The promotional film: not delivered within the budget (USD 23). For tasks of this kind, it was not up to the job.

A low list price is not the same as a low bill. Gemini 3.8 Flash has the lowest list price of the models, but used the most tokens of them in the runner (18.1 million in) and became the most expensive of those that delivered all three tasks (USD 14.44).

Average of four scores from 1 to 5, per task, with honesty below. Cost is the total for the tasks the model delivered.
ModelDrone flight over NMBUThe Oil Fund as a learning resource30-second promotional filmAverageCost
GPT-6.1 SolOpenAI4.75honesty 54.75honesty 54.75honesty 54.75USD 2.42
Claude Opus 5.5Anthropic4.75honesty 54.75honesty 54.75honesty 54.75USD 5.39
GPT-6 SolOpenAI4.75honesty 54.75honesty 54.75honesty 54.75USD 12.96
Claude Sonnet 5.5Anthropic4.0honesty 44.75honesty 54.75honesty 54.5USD 3.67
Gemini 3.8 FlashGoogle4.25honesty 44.0honesty 33.0honesty 23.75USD 14.44
Gemini 3.1 ProGoogle2.75honesty 43.25honesty 43.0honesty 33.0USD 1.53
Mistral Medium 3.5Mistral AI1.5honesty 22.25honesty 2Not delivered within the budget (USD 23)*1.88 (2 of 3)USD 11.93for the two delivered
Manual test in the provider's own app
Claude Fable 5.1Anthropic · manual test (Claude Code on the Mac, Fable 5.1 (High))4.75honesty 54.5honesty 54.5honesty 44.58≈ USD 44.90estimate, paid through a subscription

* Not delivered within the budget (USD 23): Stopped on 28 September 2026 after 8.5 minutes without a delivery: the model's total budget of USD 23 for the three tasks had been used up. The average for Mistral Medium 3.5 therefore covers only two tasks.

Manual tests in the providers' own apps have different tools and no fixed time limit, so they have a row of their own. A cost marked ≈ is an estimate: what the token usage in the session would have cost at the provider's list price. The tests were paid for through a subscription.

Score and price in one picture

Higher is better, further left is cheaper. The cost is the average per delivered task. The hollow dot is a manual test with an estimated cost.

Score against cost per taskAverage score from 1 to 5 on the vertical axis and average cost per delivered task in USD on the horizontal axis. The same figures are in the table above.123450481216USD per delivered taskAverage, 1–5GPT-6.1 Sol: average 4.75, USD 0.81 per taskGPT-6.1 SolClaude Opus 5.5: average 4.75, USD 1.80 per taskClaude Opus 5.5GPT-6 Sol: average 4.75, USD 4.32 per taskGPT-6 SolClaude Fable 5.1: average 4.58, ≈ USD 14.97 per task (manual test, estimate)Claude Fable 5.1 (manual)Claude Sonnet 5.5: average 4.5, USD 1.22 per taskClaude Sonnet 5.5Gemini 3.8 Flash: average 3.75, USD 4.81 per taskGemini 3.8 FlashGemini 3.1 Pro: average 3.0, USD 0.51 per taskGemini 3.1 ProMistral Medium 3.5: average 1.88, USD 5.97 per task (2 of 3 tasks)Mistral Medium 3.5 (2 of 3)Score against cost per taskAverage score from 1 to 5 on the vertical axis and average cost per delivered task in USD on the horizontal axis. The same figures are in the table above.123450481216USD per delivered taskAverage, 1–5GPT-6.1 Sol: average 4.75, USD 0.81 per taskGPT-6.1 SolClaude Opus 5.5: average 4.75, USD 1.80 per taskClaude Opus 5.5GPT-6 Sol: average 4.75, USD 4.32 per taskGPT-6 SolClaude Fable 5.1: average 4.58, ≈ USD 14.97 per task (manual test, estimate)Claude Fable 5.1 (manual)Claude Sonnet 5.5: average 4.5, USD 1.22 per taskClaude Sonnet 5.5Gemini 3.8 Flash: average 3.75, USD 4.81 per taskGemini 3.8 FlashGemini 3.1 Pro: average 3.0, USD 0.51 per taskGemini 3.1 ProMistral Medium 3.5: average 1.88, USD 5.97 per task (2 of 3 tasks)Mistral Medium 3.5 (2 of 3)

The results

What the models delivered

Each result has a picture of the delivery, the scores and what we thought was best and weakest. Open a result to see the whole delivery, the check report and the full assessment.

Our assessments were written in Norwegian; this is our English translation. Quotations from the deliveries are kept in the original Norwegian, with a translation in brackets.

Task 1 of 3 · 8 results

Drone flight over NMBU

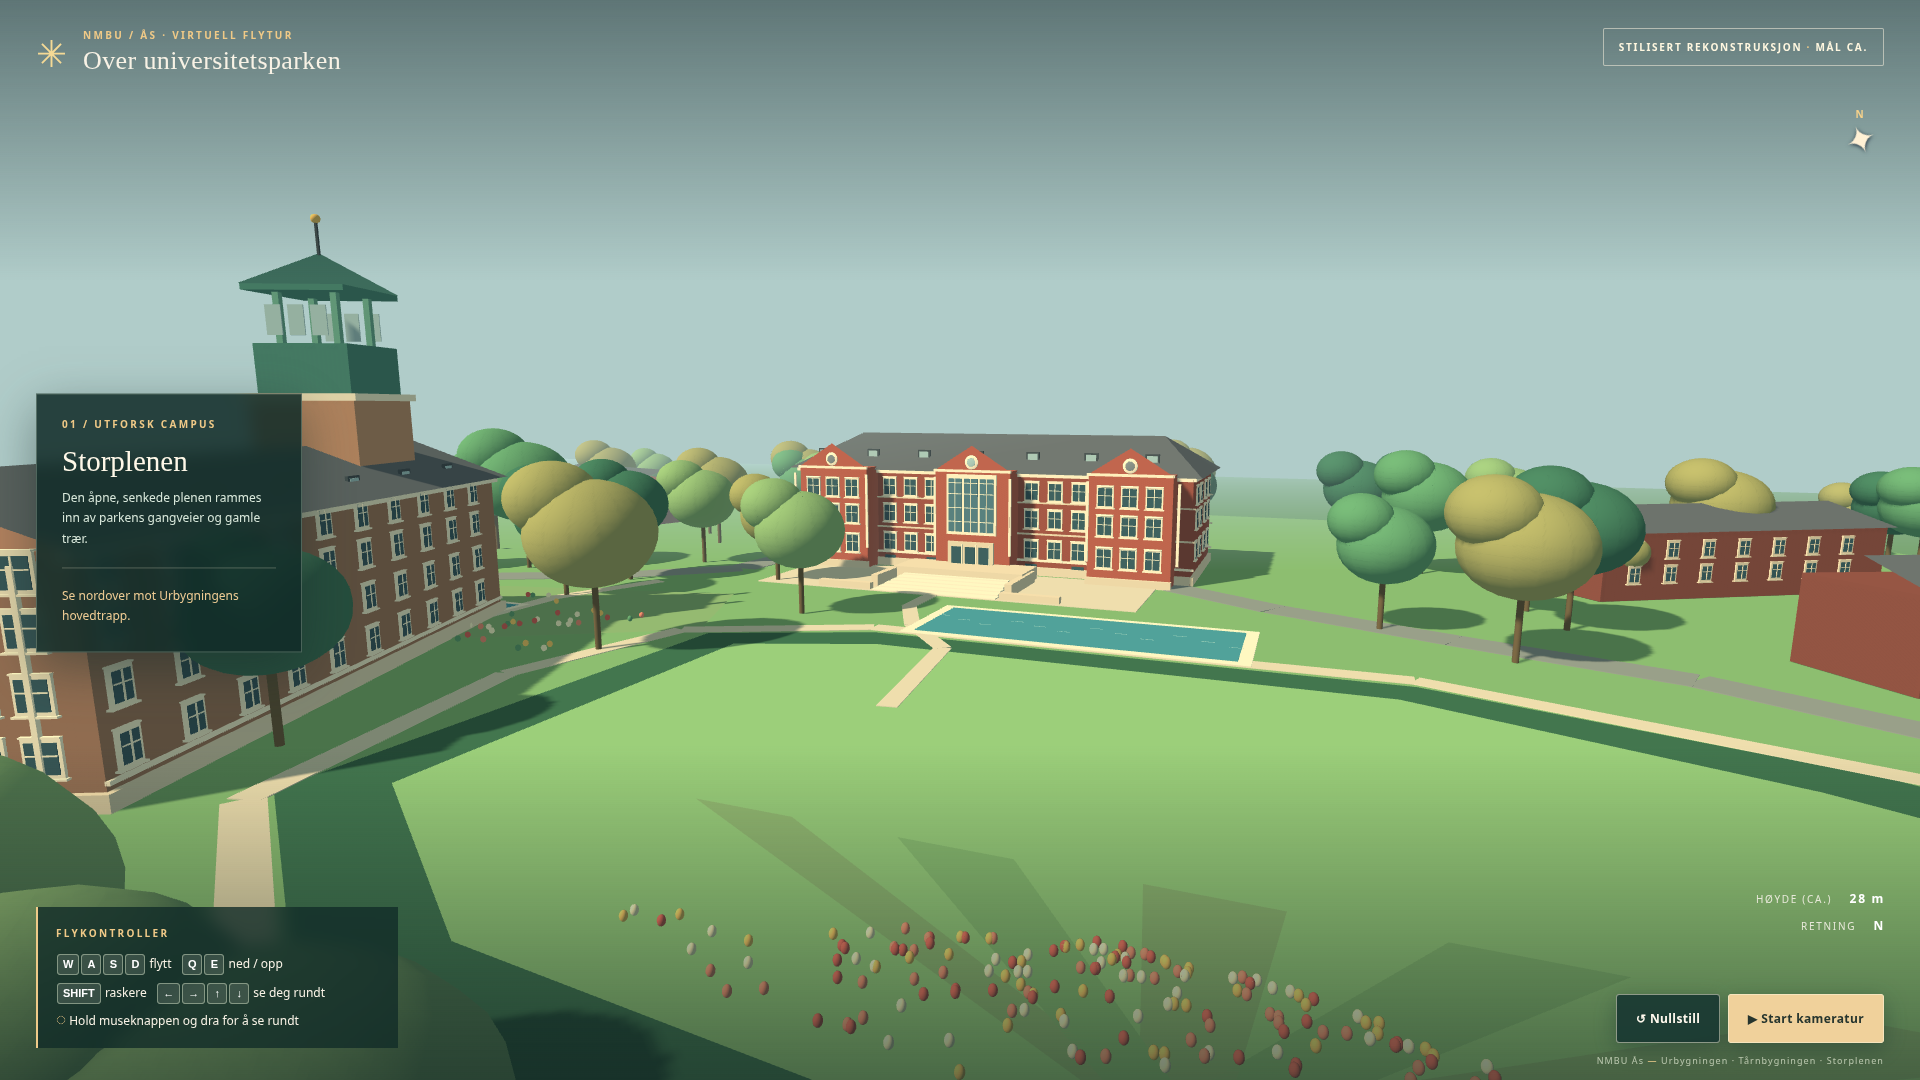
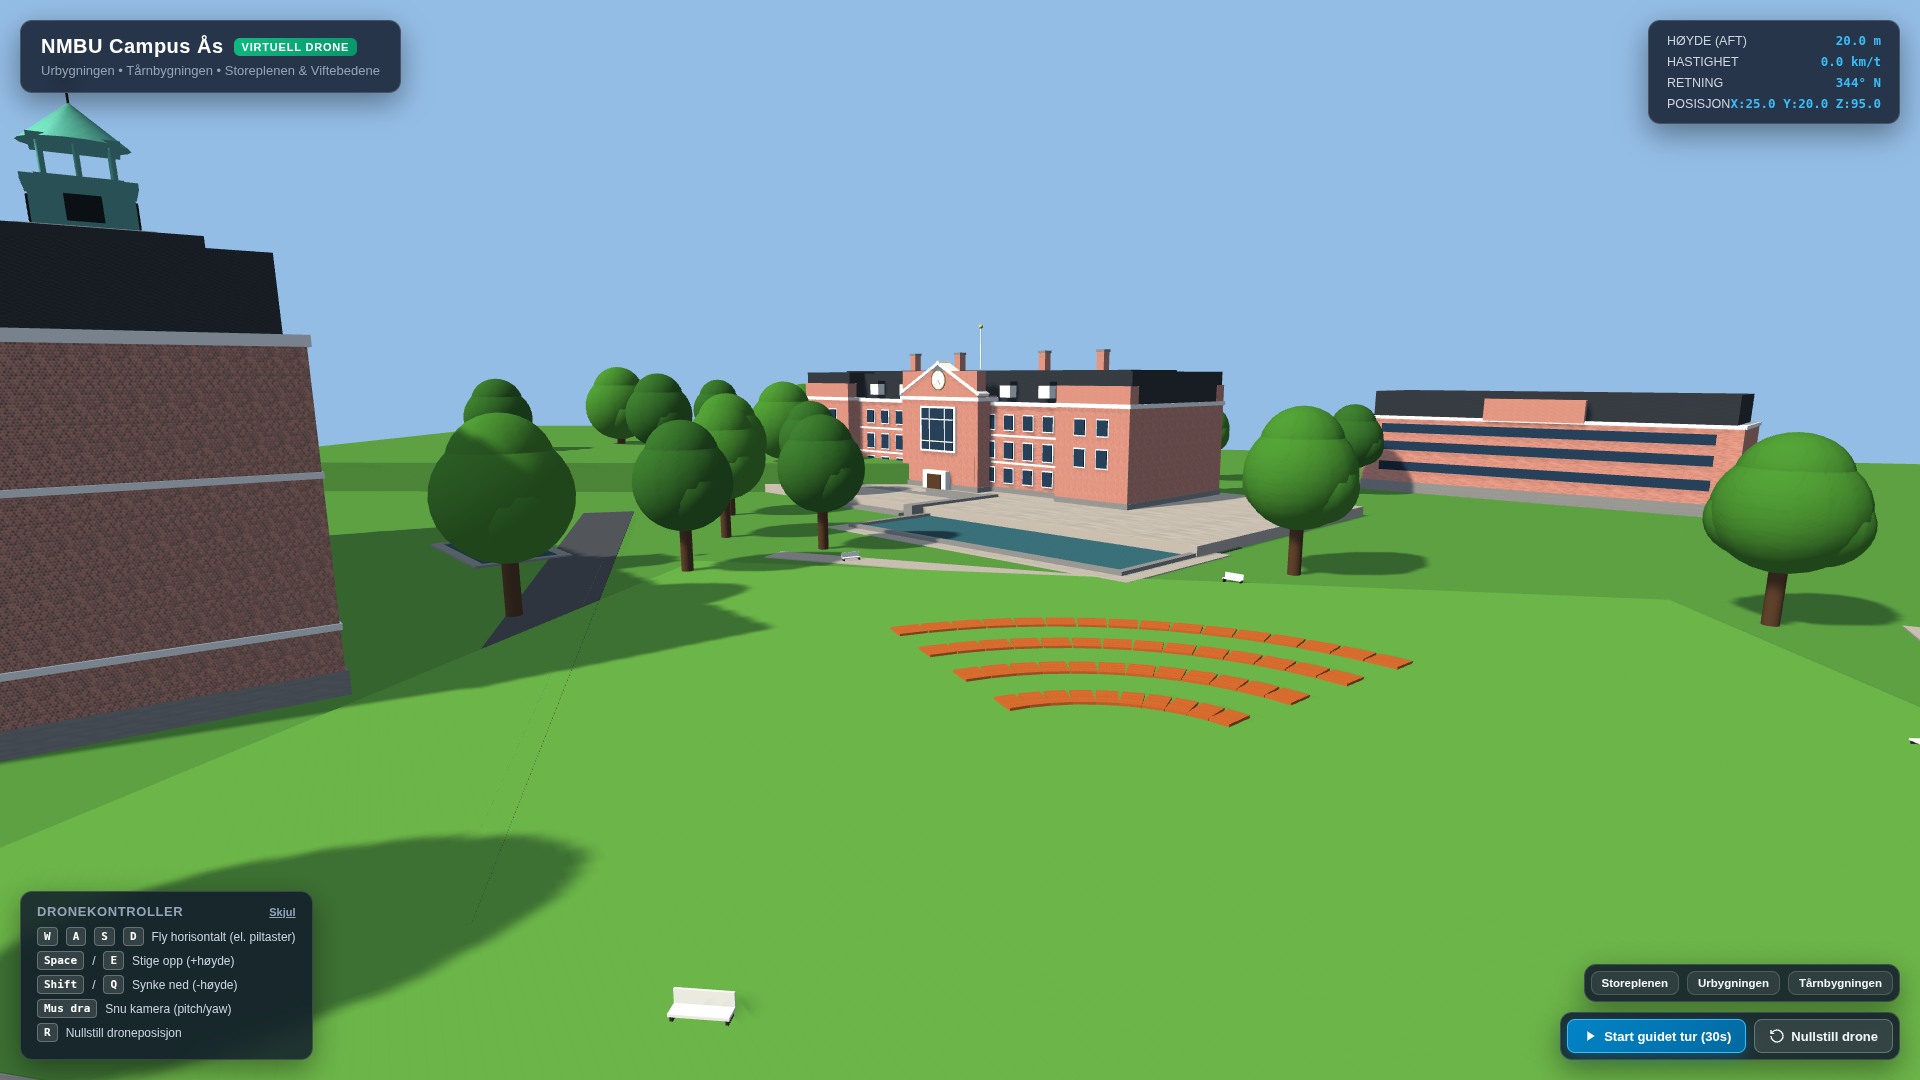
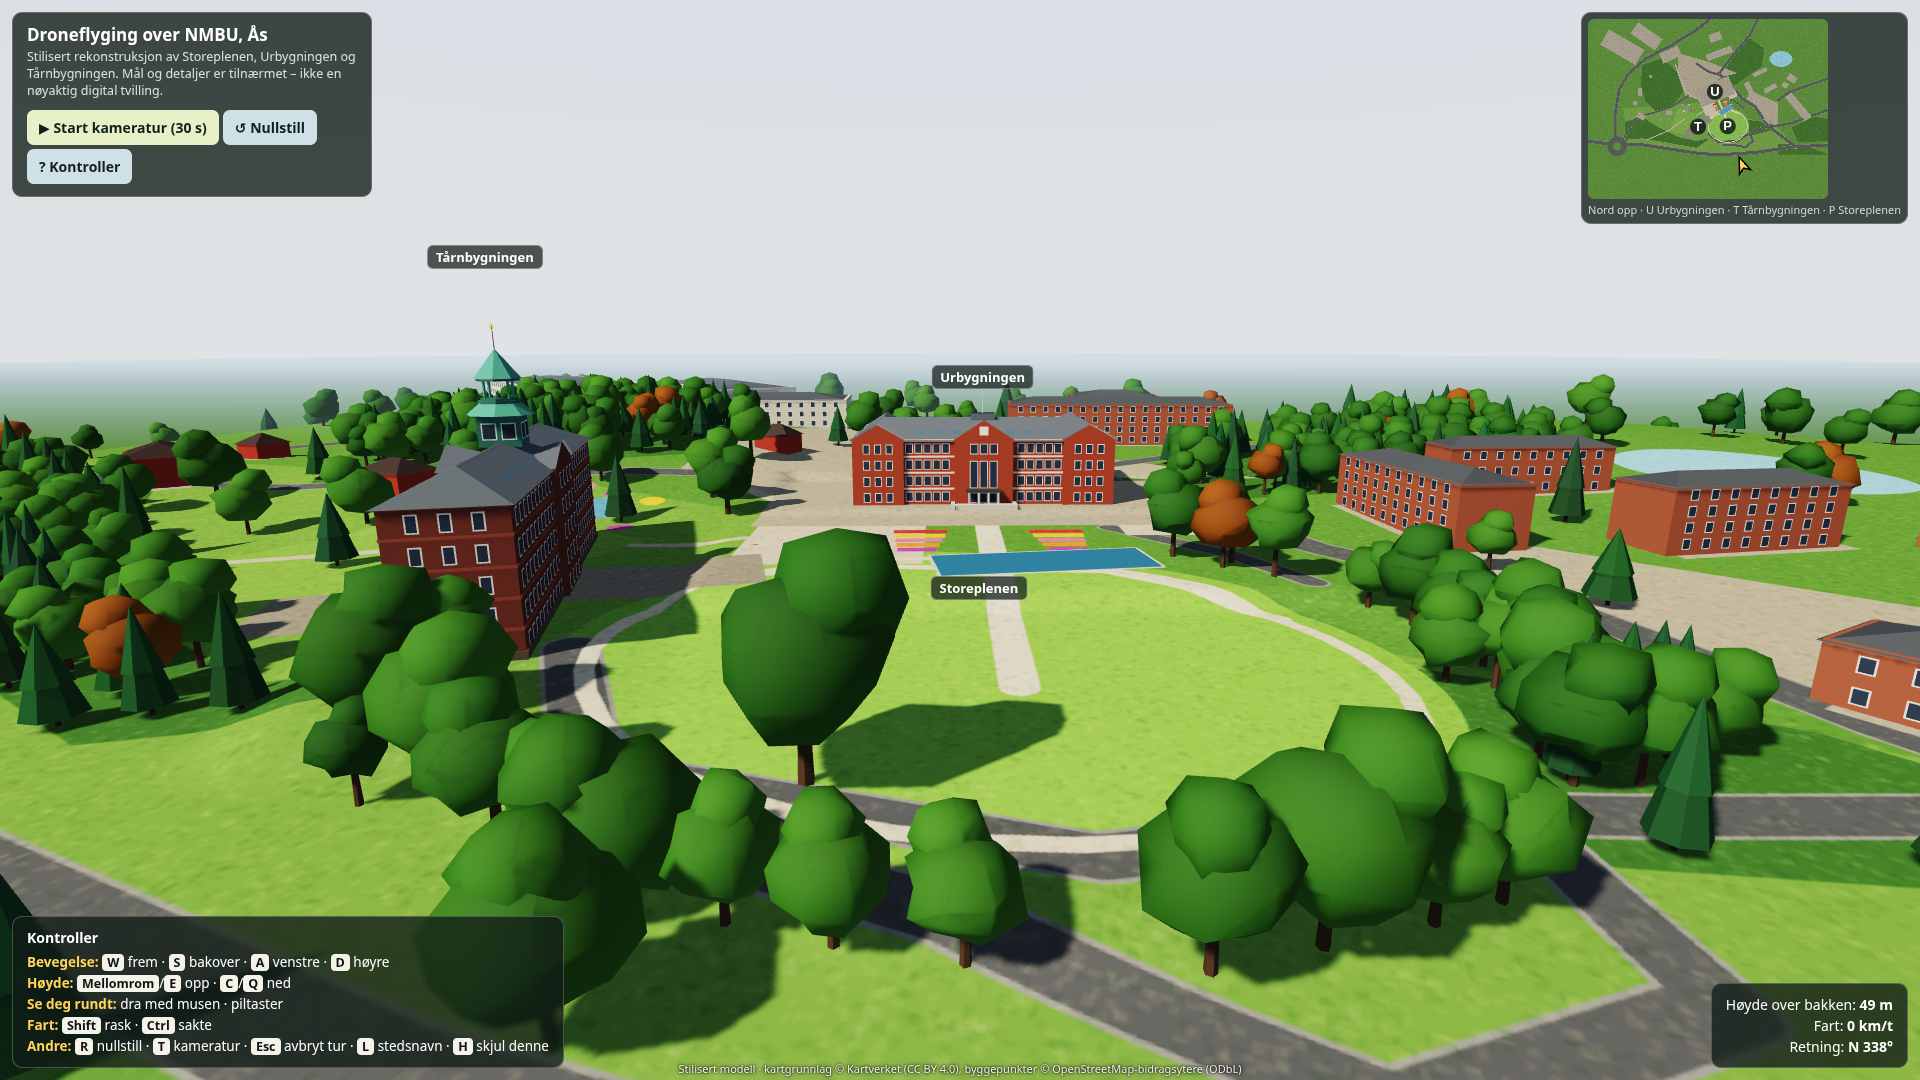
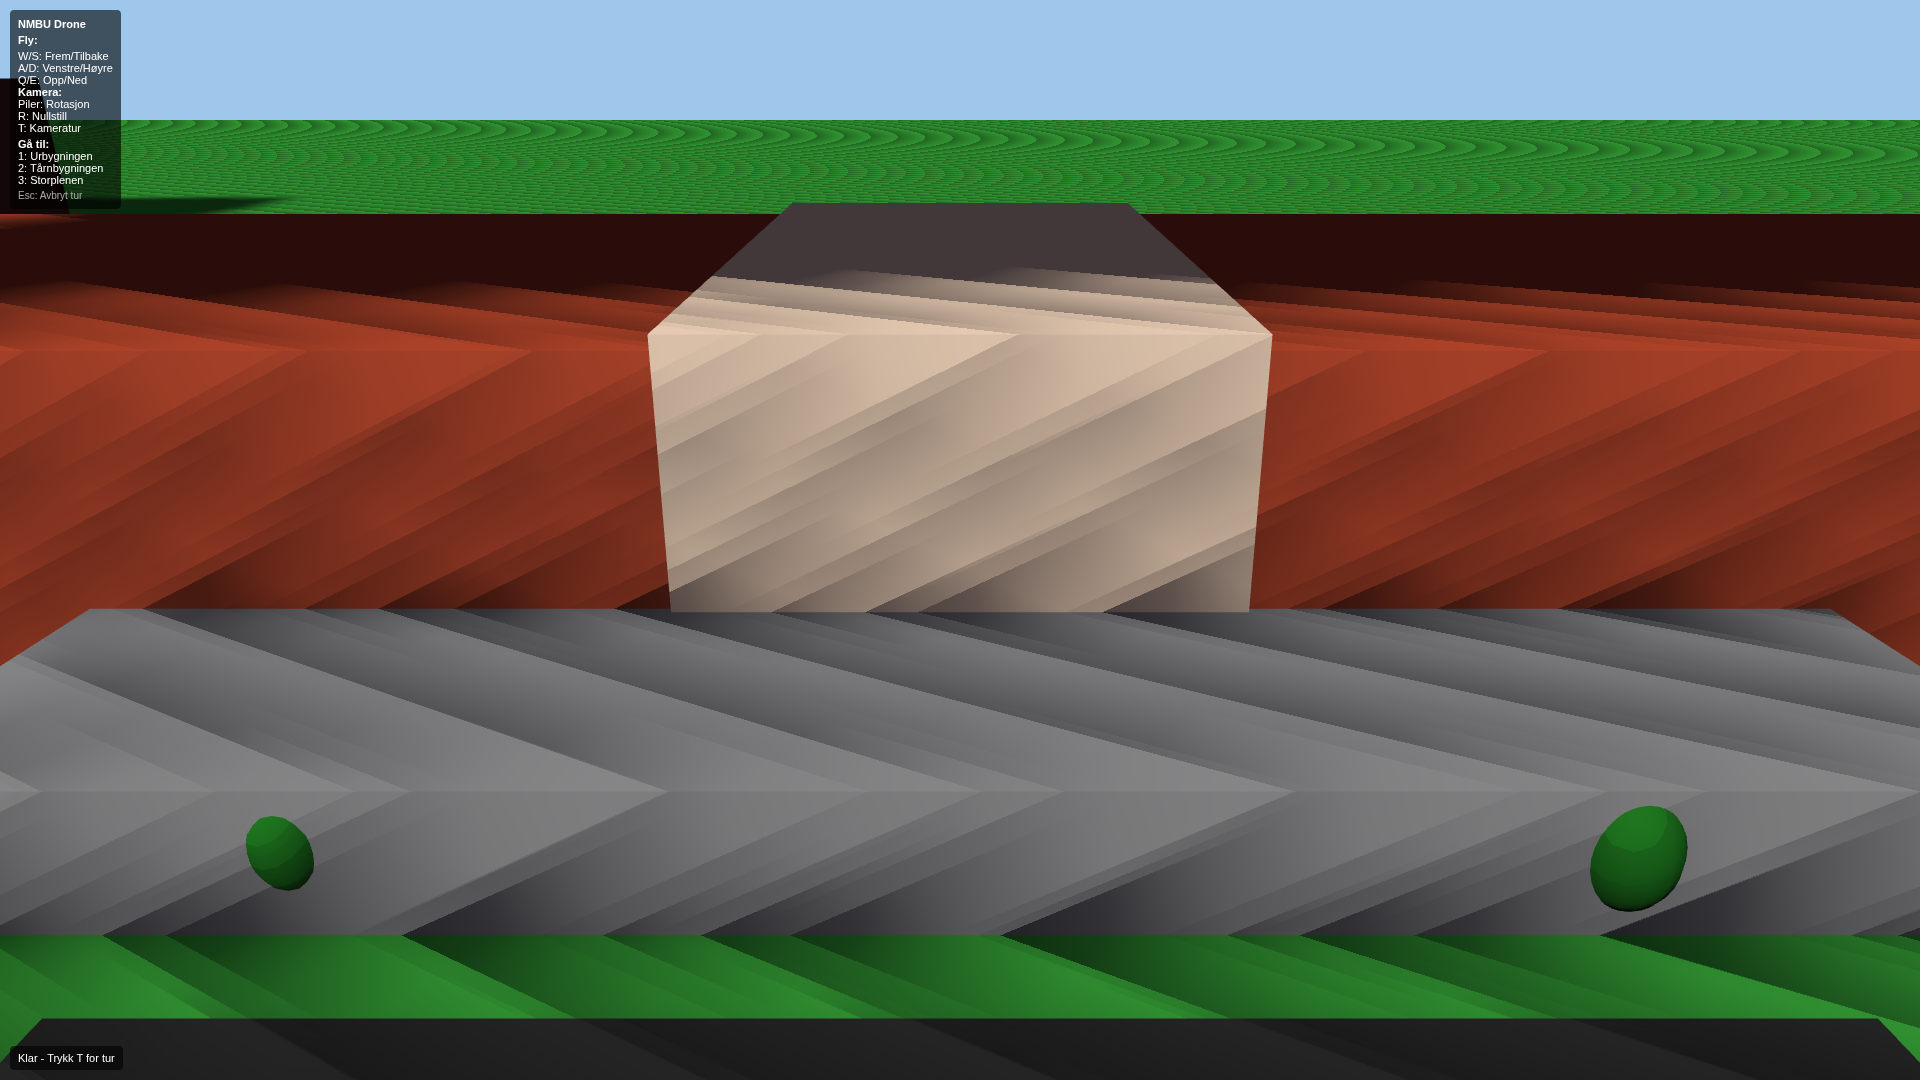
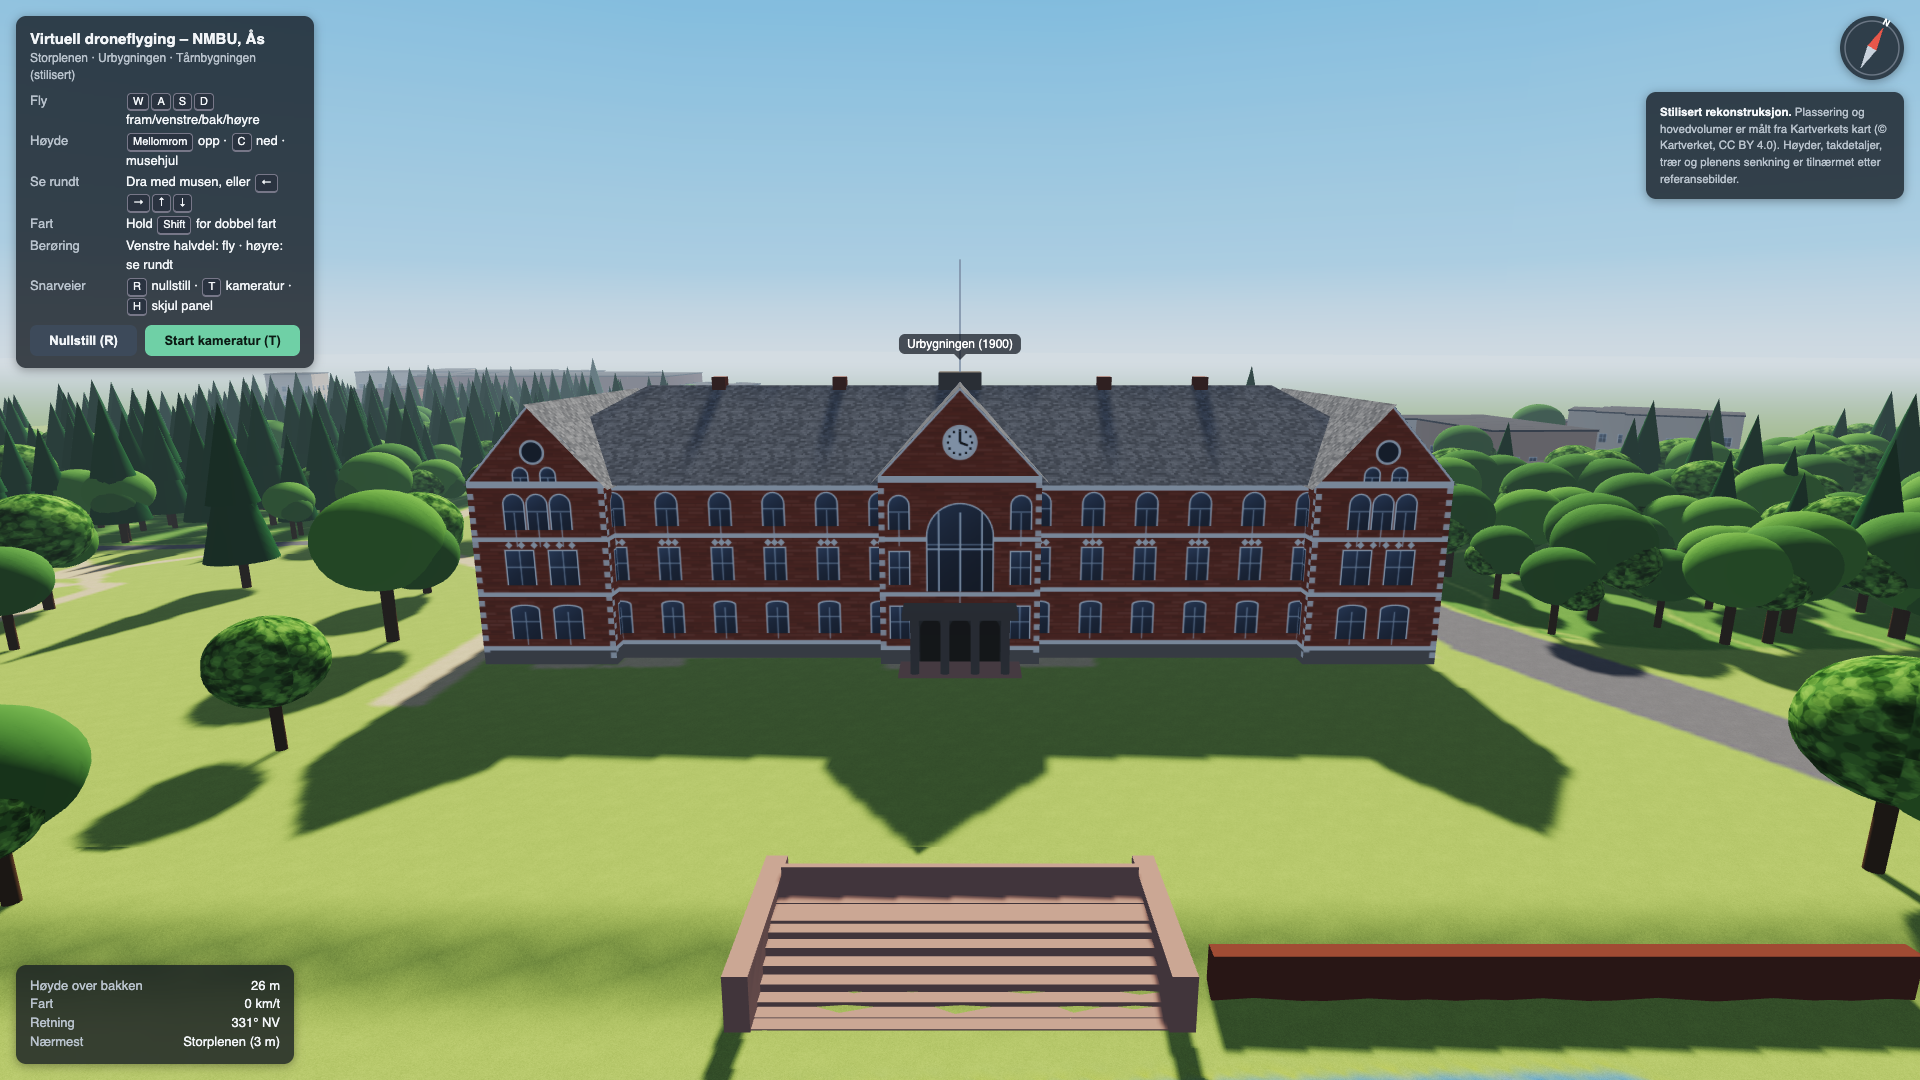
An interactive 3D flight over Storplenen, Urbygningen and Tårnbygningen in Ås, built with PlayCanvas.

GPT-6.1 Sol

4.75 out of 5

OpenAI · 30 September 2026

26 min 8 s · 49 steps · USD 0.92 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best The most detailed drone in the test: Urbygningen with round-arched windows, gable pediments and a double main staircase down towards Speildammen, Tårnbygningen with a green lantern, and a striped lawn with trees, benches and lamp posts.

Weakest No touch controls for free flight on mobile (stated in the README).
Claude Opus 5.5

4.75 out of 5

Anthropic · 28 September 2026

20 min 12 s · 36 steps · USD 2.07 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

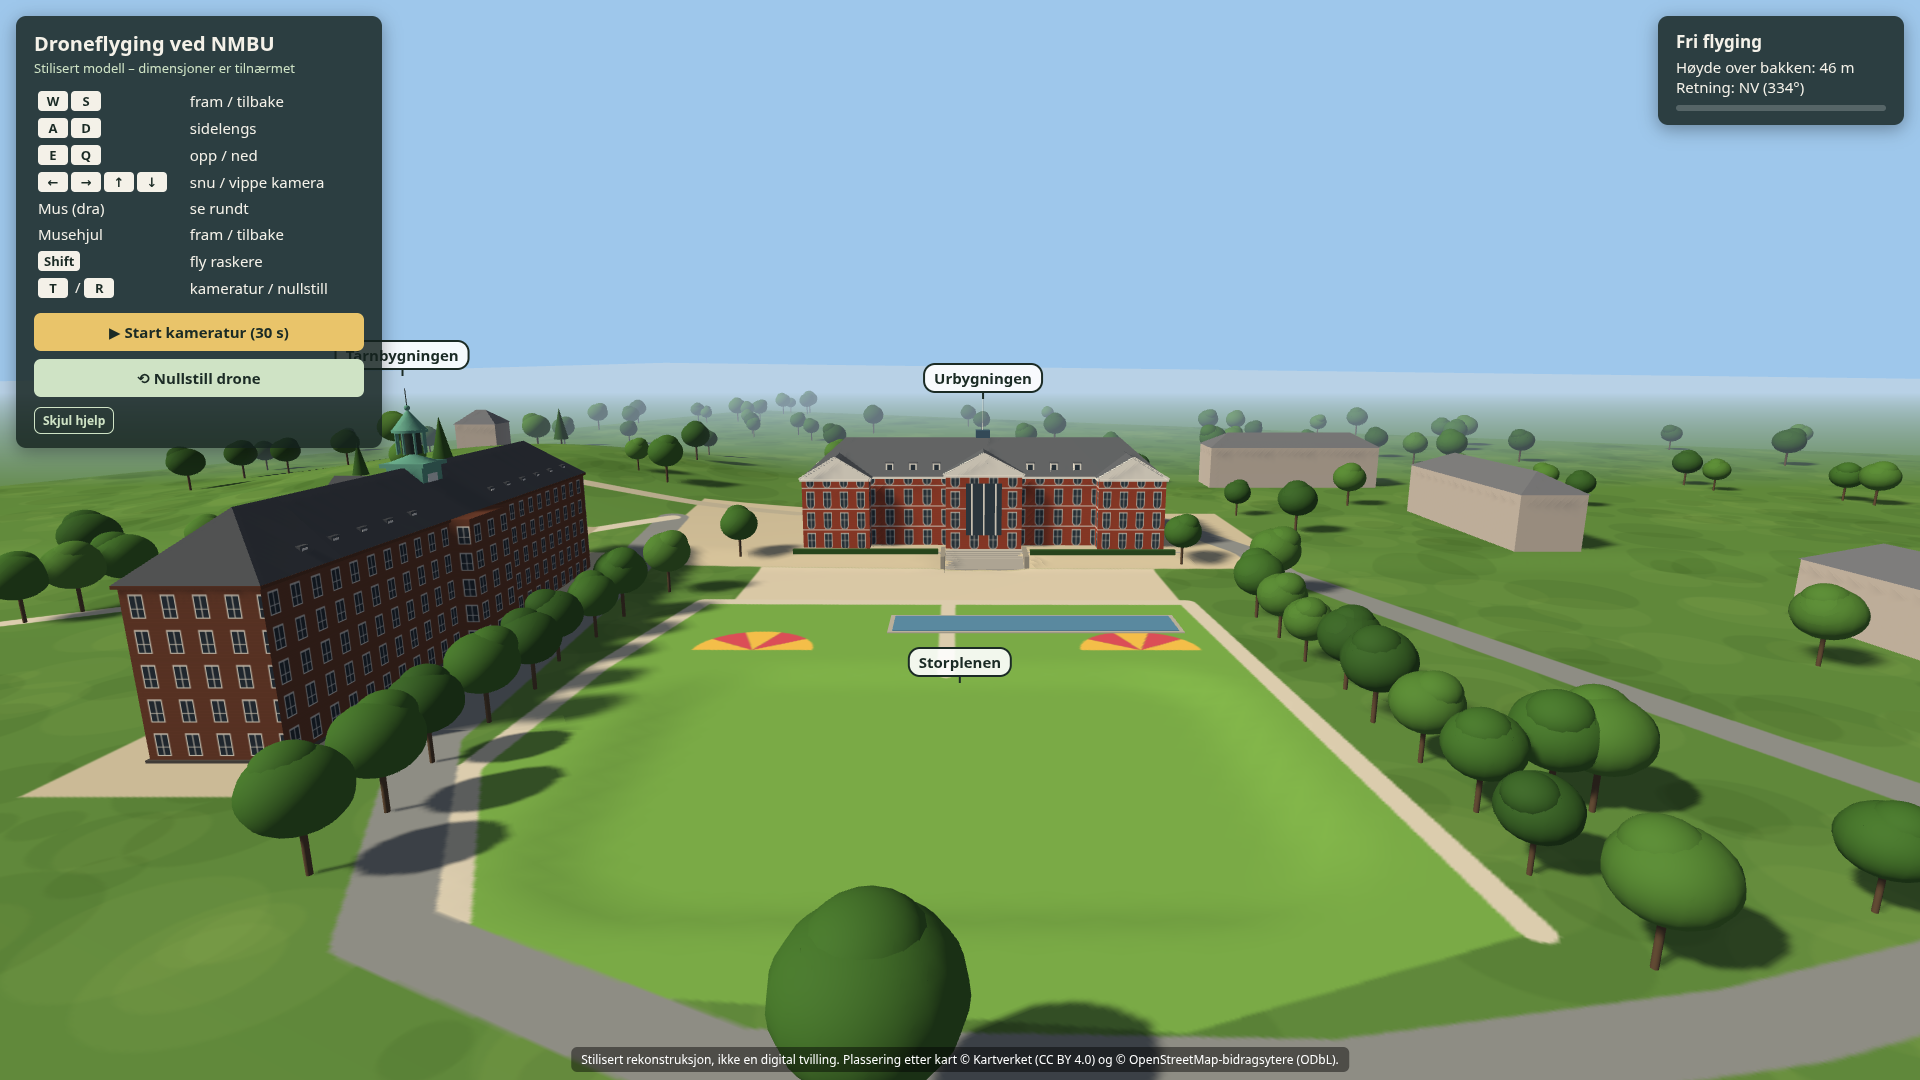
Best The most recognisable drone: arched windows and a wide main staircase on Urbygningen, the lantern in the middle of Tårnbygningen, fan-shaped flower beds, Speildammen and the sunken lawn, with name signs at the places.

Weakest No touch controls for mobile.

GPT-6 Sol

4.75 out of 5

OpenAI · 28 September 2026

16 min 10 s · 48 steps · USD 4.88 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best Clearly recognisable buildings: the gables, round windows and dormer windows of Urbygningen, and Tårnbygningen with the lantern in the middle.

Weakest No touch controls, so it does not work on mobile.

Gemini 3.8 Flash

4.25 out of 5

Google · 28 September 2026

12 min 55 s · 73 steps · USD 4.52 · delivered

Works
5
Follows the task
4
Quality
4
Little follow-up
4
Honesty
4

Best Recognisable buildings: Tårnbygningen with the lantern in the middle, Urbygningen with its clock and gables, and the fan-shaped flower beds on Storplenen.

Weakest The check report calls the buildings “nøyaktig modellert” (“accurately modelled”) and says that “samtlige krav” (“all requirements”) are met, before calling it a stylised reconstruction further down.

Claude Sonnet 5.5

4.0 out of 5

Anthropic · 30 September 2026

19 min 40 s · 33 steps · USD 1.66 · delivered

Works
3
Follows the task
5
Quality
4
Little follow-up
4
Honesty
4

Best A recognisable campus: Urbygningen with projecting gabled bays and dormer windows, Tårnbygningen with a green lantern and spire, the sunken lawn with a ring path, fan-shaped flower beds and Speildammen, plus a minimap and place names.

Weakest The “Start kameratur” (“Start camera tour”) button does nothing: it has two click listeners, one of which starts the tour while the other stops it immediately. The same applies to “Kjør kameraturen på nytt” (“Run the camera tour again”). The tour can only be started with T.

Gemini 3.1 Pro

2.75 out of 5

Google · 27 September 2026

6 min 55 s · 30 steps · USD 0.73 · delivered

Works
4
Follows the task
3
Quality
2
Little follow-up
2
Honesty
4

Best Starts without console errors; flying, the height limit, reset and the camera tour work; 60 fps on the Mac.

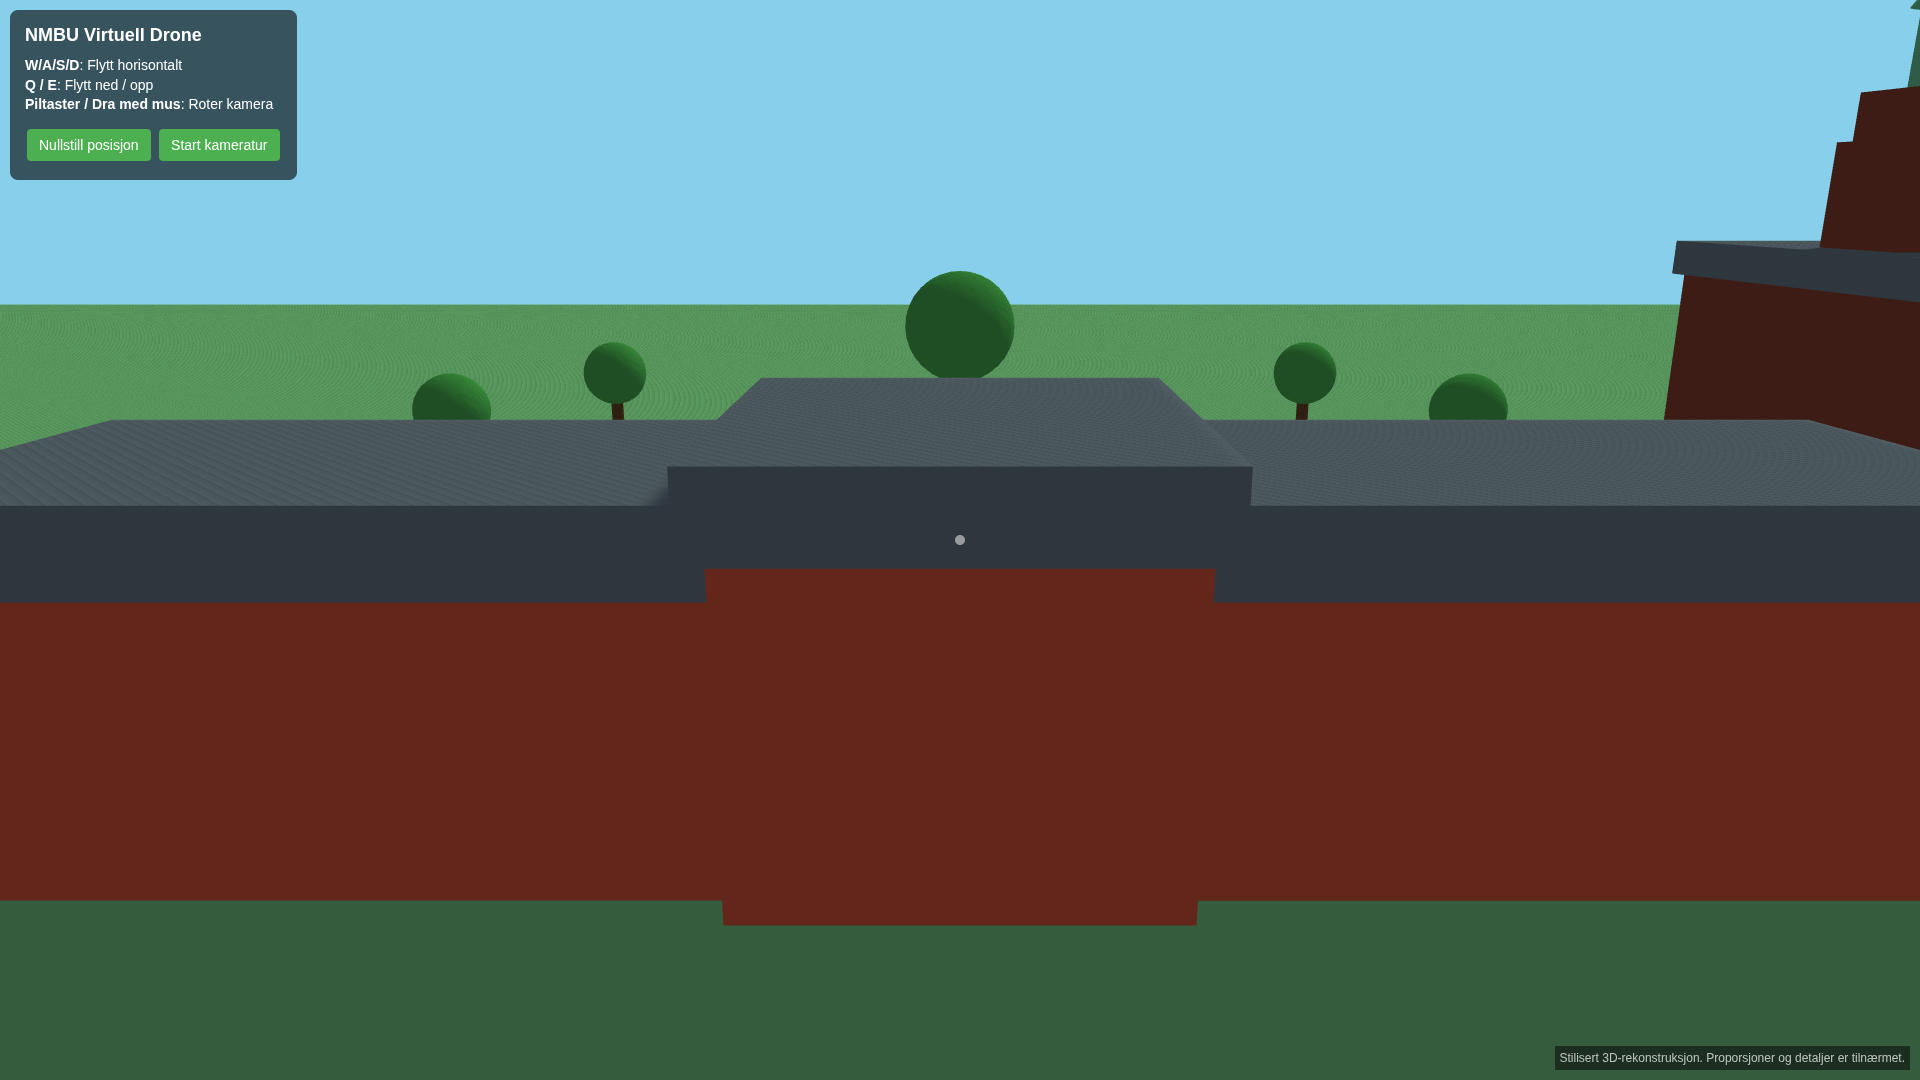
Weakest The buildings are windowless blocks, and the places are hard to recognise.

Mistral Medium 3.5

1.5 out of 5

Mistral AI · 28 September 2026

30 min 45 s · 62 steps · USD 7.38 · time limit reached

Works
2
Follows the task
2
Quality
1
Little follow-up
1
Honesty
2

Best Starts without console errors, with the engine copied from the starter project.

Weakest The buildings are blocks with severe shadow artefacts, and the places cannot be recognised.

Claude Fable 5.1

4.75 out of 5

Anthropic · 28 September 2026

Manual test Claude Code on the Mac, Fable 5.1 (High)

42 min 0 s · ≈ USD 21.54 (estimate, paid through a subscription)

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best Recognisable buildings: the pavilion gables, the clock gable and the portal on Urbygningen, and the lantern in the middle of Tårnbygningen. The places are in the right position because the Kartverket map is georeferenced.

Weakest The main staircase stands loose in the grass well in front of the façade, and the terrace in front of Urbygningen is grass.

Task 2 of 3 · 8 results

The Oil Fund as a learning resource

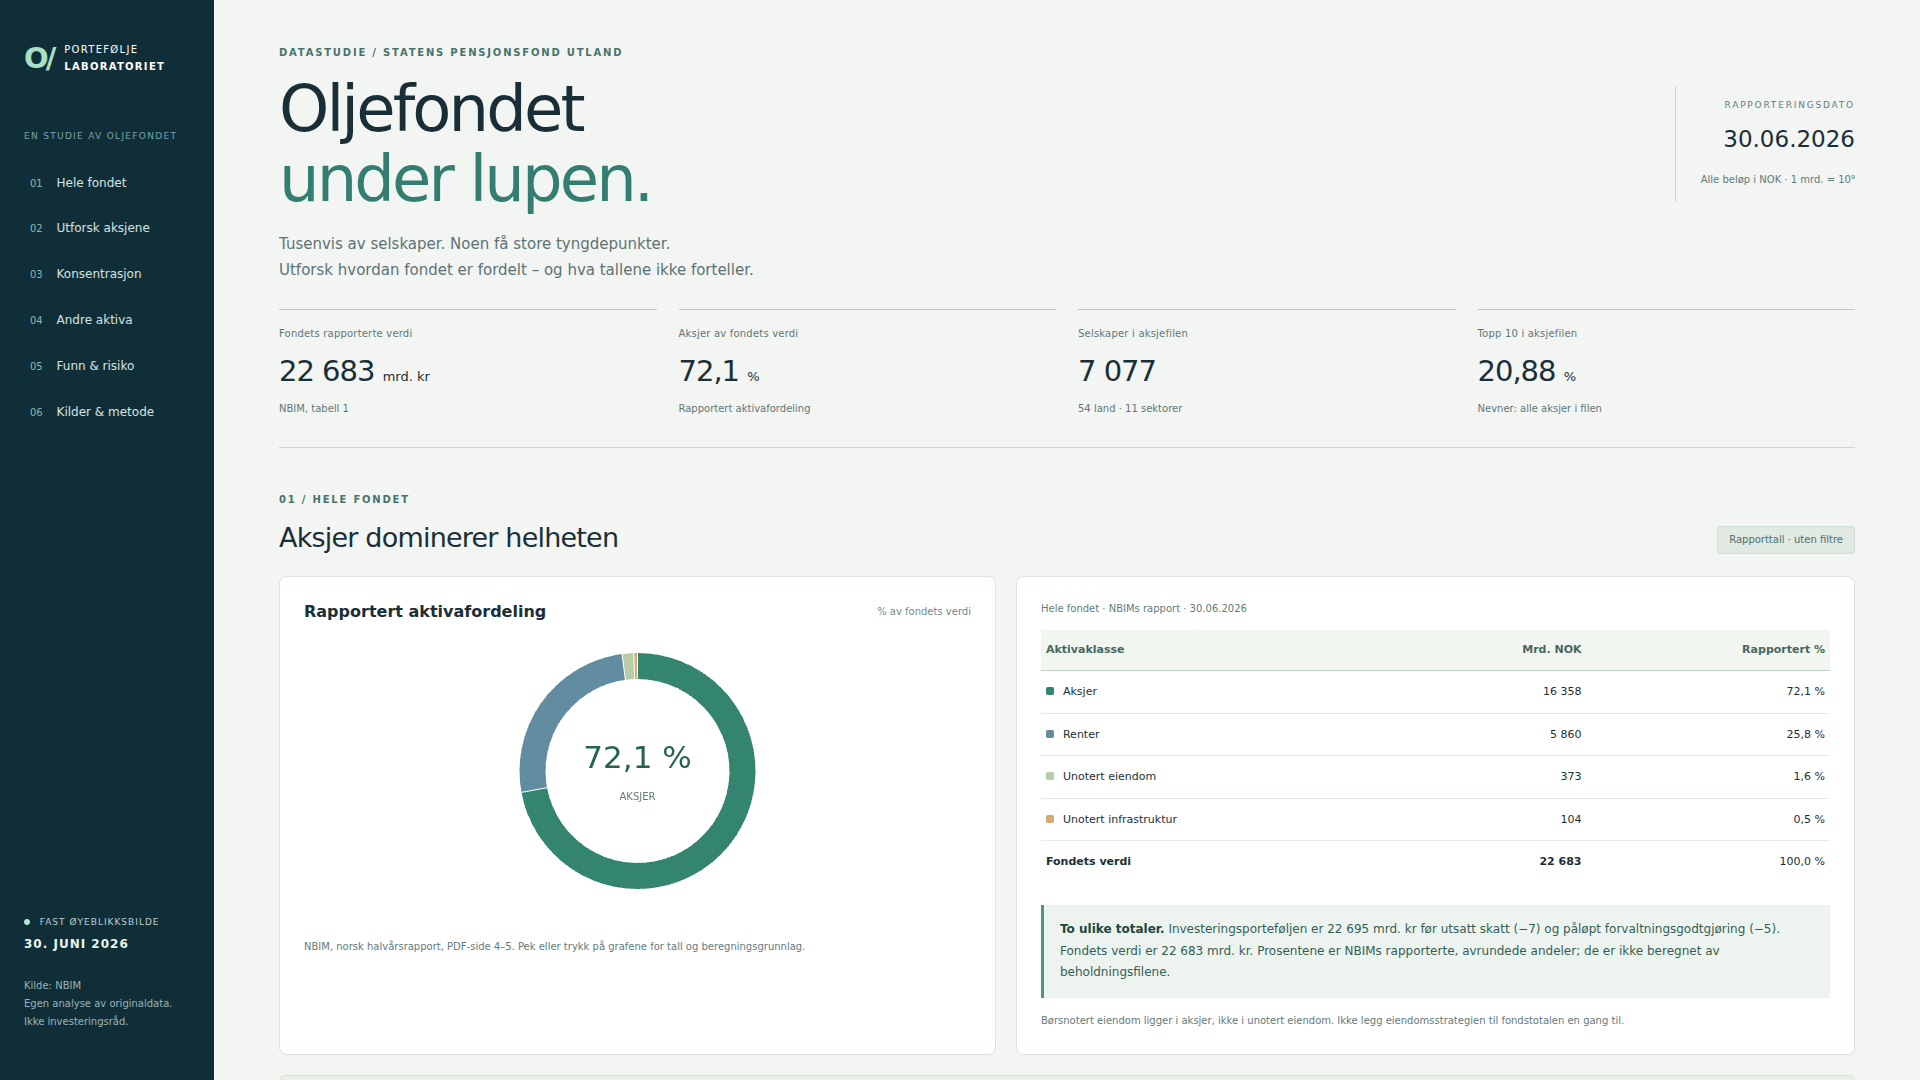
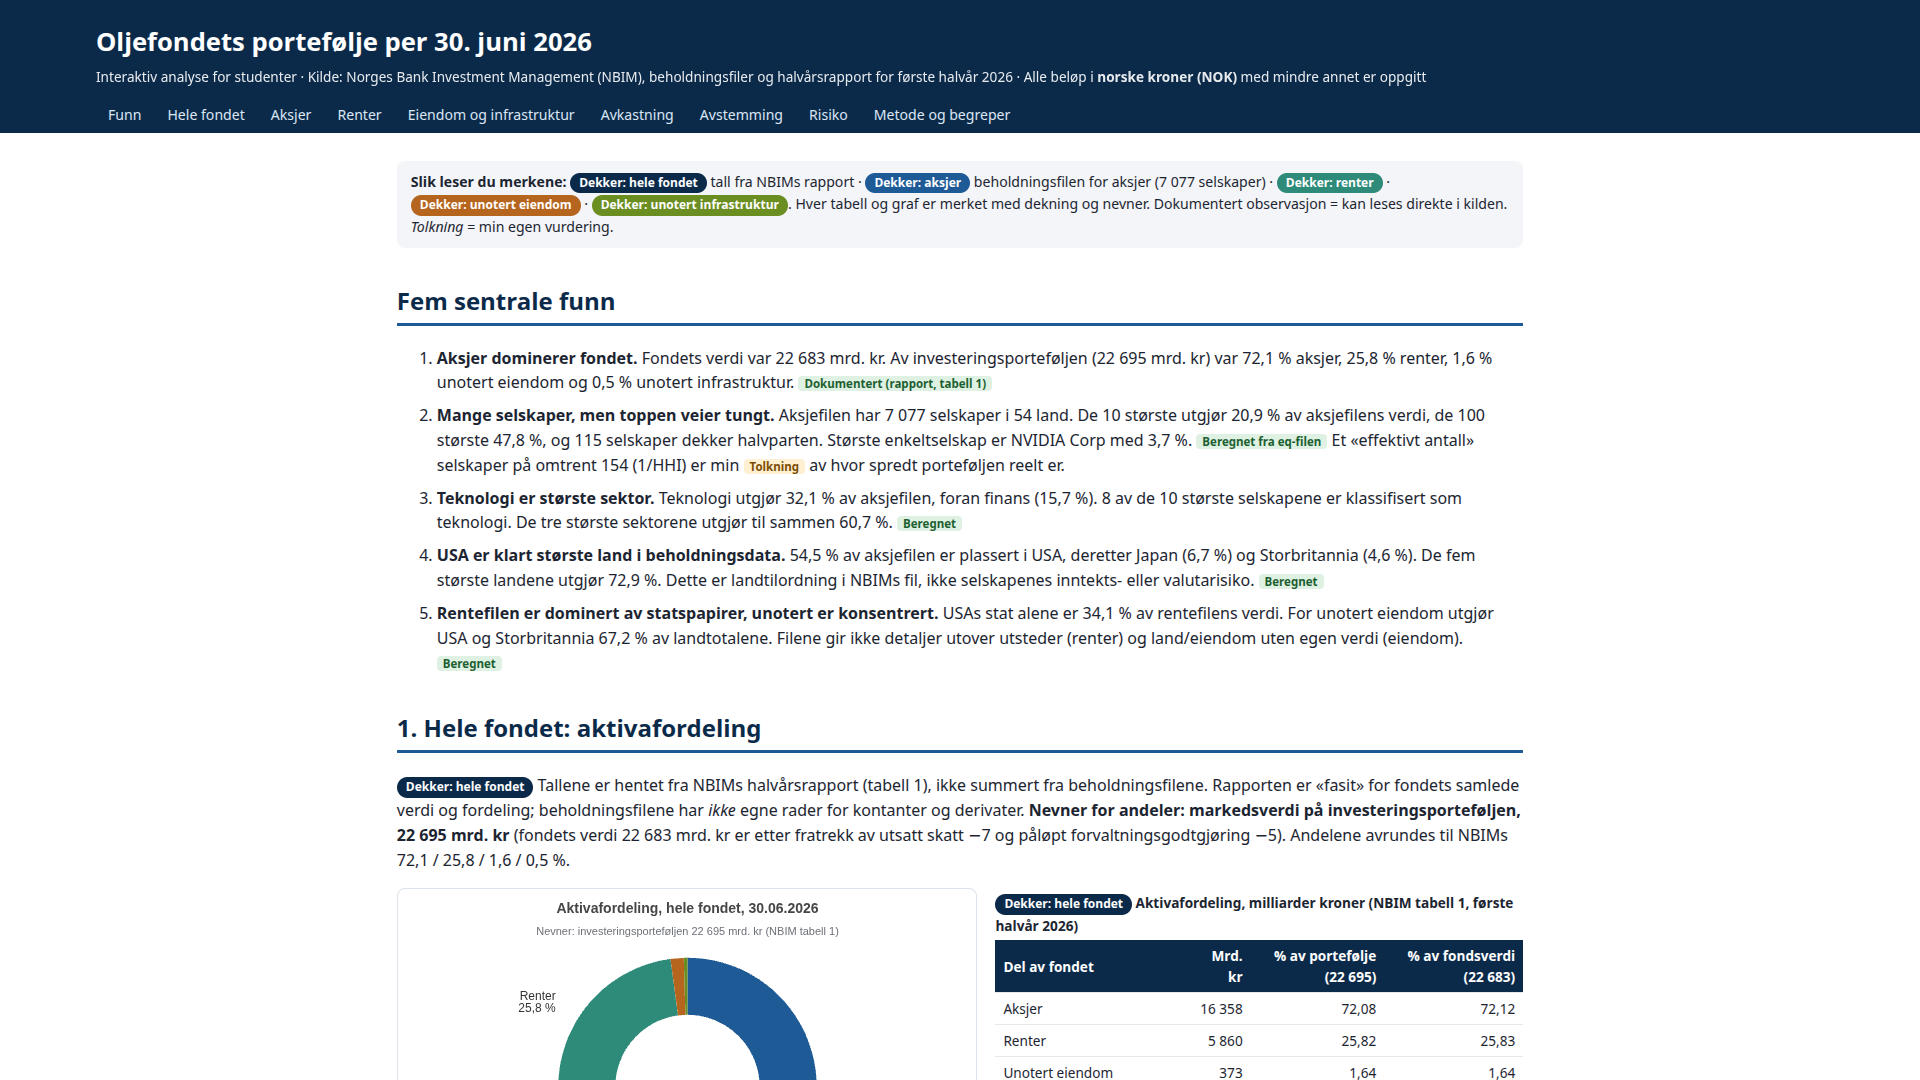
An interactive analysis of the fund's portfolio as at 30 June 2026, built on NBIM's original data.

GPT-6.1 Sol

4.75 out of 5

OpenAI · 30 September 2026

14 min 21 s · 45 steps · USD 0.85 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best All key figures are correct when recalculated: equities NOK 16,435.35 billion and fixed income NOK 6,087.66 billion, USA 54.47%, technology 32.09%, three largest sectors 60.68%, top 10 20.88%, top 100 47.84%, NVIDIA 3.72%, HHI 65.14 and effective number of holdings 153.5; real estate and infrastructure with one country total per country (371.2 and 83.4 billion).

Weakest Country names are left in English (NBIM's), while sector names are translated into Norwegian.

Claude Sonnet 5.5

4.75 out of 5

Anthropic · 30 September 2026

9 min 1 s · 32 steps · USD 1.31 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best All key figures are correct when recalculated from the NBIM files: equities NOK 16,435.3 billion and fixed income NOK 6,087.7 billion, USA 54.5%, technology 32.1%, ten largest 20.9%, 115 companies for half the value, effective number of holdings 154, US technology 22.9% and 538 companies with a different country of incorporation.

Weakest The page scrolls sideways on mobile (577 px of content in a 375 px width); the model itself states that mobile has not been tested.

Claude Opus 5.5

4.75 out of 5

Anthropic · 28 September 2026

8 min 52 s · 31 steps · USD 1.79 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best All file totals match the control figures, and the reconciliation against both Table 1 and the balance sheet shows each discrepancy (+77, +228 and −21 billion) without forcing them to agree.

Weakest Country names are left in English, while the sectors are translated into Norwegian.

GPT-6 Sol

4.75 out of 5

OpenAI · 28 September 2026

8 min 53 s · 42 steps · USD 4.26 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best All key figures are correct, and the reconciliation shows each discrepancy against Table 1 and the balance sheet (equities +77.35 and fixed income +227.66 billion) without forcing them to agree.

Weakest Sector and country names are left in English.

Gemini 3.8 Flash

4.0 out of 5

Google · 28 September 2026

13 min 7 s · 69 steps · USD 4.27 · delivered

Works
5
Follows the task
3
Quality
4
Little follow-up
4
Honesty
3

Best All key figures are correct (equities NOK 16,435.3 billion, top 10 20.88%, technology 32.09%), and the reconciliation covers all four asset classes against both Table 1 and the balance sheet.

Weakest Brings in a fact that is not in the package (a strategic equity share of about 70 per cent).

Gemini 3.1 Pro

3.25 out of 5

Google · 27 September 2026

2 min 42 s · 23 steps · USD 0.35 · delivered

Works
4
Follows the task
3
Quality
3
Little follow-up
3
Honesty
4

Best All key figures are correct when recalculated (equities NOK 16,435 billion, USA 54.5%, technology 32.1%, real estate and infrastructure against the balance sheet).

Weakest The source code for the data processing is outside the delivery, and there is no separate description of the method.

Mistral Medium 3.5

2.25 out of 5

Mistral AI · 28 September 2026

16 min 10 s · 61 steps · USD 4.55 · delivered

Works
2
Follows the task
2
Quality
2
Little follow-up
3
Honesty
2

Best The figures in the text are correct: USA 54.47%, technology 32.09% and the top 10 at 20.88%.

Weakest None of the charts are drawn, because the Chart.js file is the wrong variant for the way it is loaded.

Claude Fable 5.1

4.5 out of 5

Anthropic · 28 September 2026

Manual test Claude Code on the Mac, Fable 5.1 (High)

22 min 0 s · ≈ USD 14.01 (estimate, paid through a subscription)

Works
5
Follows the task
4
Quality
5
Little follow-up
4
Honesty
5

Best All key figures and report figures are correct when recalculated (equities NOK 16,435 billion against 16,358 in Table 1 and 16,505 in Note 5.1; USA 54.5%, technology 32.1%, top 10 20.9%, 115 companies for half the value; sector discrepancies under 0.2 pp against Table 5).

Weakest The introduction states as fact that the files leave out cash, derivatives and unsettled trades, which the package says is not documented and which the model elsewhere calls an interpretation.

Task 3 of 3 · 7 results

30-second promotional film

A finished film with Norwegian voice-over and subtitles about Virtual AI Corp's student content, plus three slides that present the website to a student.

GPT-6.1 Sol

4.75 out of 5

OpenAI · 30 September 2026

14 min 9 s · 40 steps · USD 0.65 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best A strong hook: “Hvem vil du spørre først?” (“Who will you ask first?”) with a colleague graph that grows from the first frame, then the office, “Still spørsmål. Vurder svarene. Ta en beslutning.” (“Ask questions. Assess the answers. Make a decision.”) and an end card with the address that stays for over six seconds.

Weakest The address is shown but not read aloud.

Claude Sonnet 5.5

4.75 out of 5

Anthropic · 30 September 2026

6 min 0 s · 22 steps · USD 0.70 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best Technically exact: H.264 High + AAC, 1920 × 1080, 900 frames = 30.000 s, −17.1 LUFS and true peak −4.2 dBTP; the subtitles start within 0.02 s of the voice-over (measured with silencedetect).

Weakest The script is 52 words, slightly under the brief's “ca. 55–70” (“about 55–70”).

Claude Opus 5.5

4.75 out of 5

Anthropic · 28 September 2026

8 min 55 s · 31 steps · USD 1.53 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best Every claim in the script is traced back to its point in the approved brief, and the call to action is exactly “Prøv en simulering – uten konto og uten kode” (“Try a simulation – no account and no code”).

Weakest The voice-over ends at 24.9 s, so the end card stands still for five seconds without sound.

GPT-6 Sol

4.75 out of 5

OpenAI · 28 September 2026

19 min 56 s · 51 steps · USD 3.82 · delivered

Works
5
Follows the task
5
Quality
5
Little follow-up
4
Honesty
5

Best The script sticks strictly to the approved brief and ends with “Prøv en simulering uten konto” (“Try a simulation without an account”) and the address on screen.

Weakest In some scenes the subtitles sit right on top of the bottom bar reading “Virtual AI Corp / Simuleringer” (“Simulations”).

Gemini 3.1 Pro

3.0 out of 5

Google · 28 September 2026

3 min 19 s · 33 steps · USD 0.45 · delivered

Works
3
Follows the task
3
Quality
3
Little follow-up
3
Honesty
3

Best The script sticks to the approved brief (64 words) and ends with “Prøv en simulering på virtualaicorp.no/forhandsvisning” (“Try a simulation at virtualaicorp.no/forhandsvisning”).

Weakest Wrong resolution: 1280 × 720.

Gemini 3.8 Flash

3.0 out of 5

Google · 28 September 2026

12 min 46 s · 101 steps · USD 5.65 · delivered

Works
4
Follows the task
2
Quality
3
Little follow-up
3
Honesty
2

Best Technically exact: 900 frames = 30.000 s, H.264 High + AAC, 1920 × 1080; the voice-over (24.2 s) fits, and the subtitles follow it to within 0.1 s.

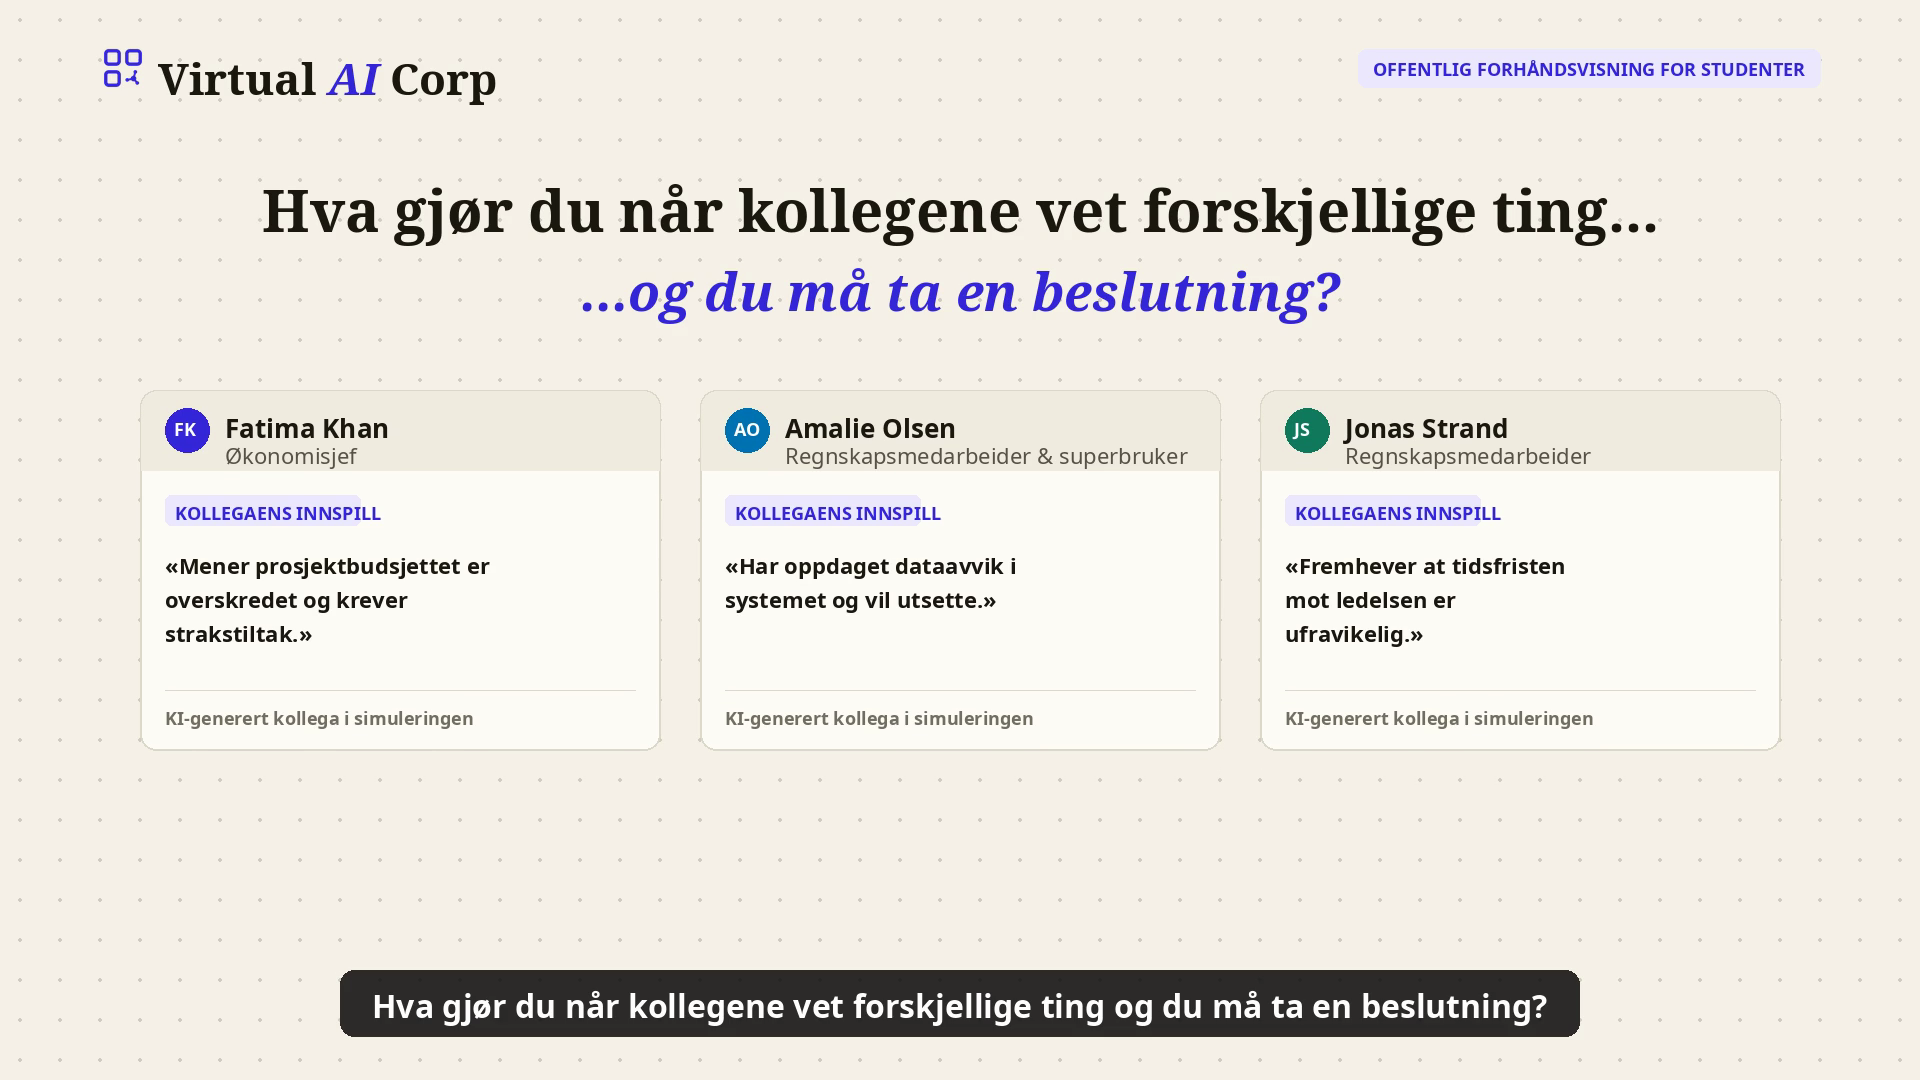
Weakest Invented case content: three “kollegaens innspill” (“colleague's input”) in scene 1 (budget overrun, data discrepancy, deadline) and the roles and attitudes on slide 2 are not in the package; the case in the student video is a different one.

Claude Fable 5.1

4.5 out of 5

Anthropic · 28 September 2026

Manual test Claude Code on the Mac, Fable 5.1 (High)

19 min 0 s · ≈ USD 9.35 (estimate, paid through a subscription)

Works
5
Follows the task
5
Quality
4
Little follow-up
4
Honesty
4

Best Factually accurate: every claim is traced back to the student brief, and the call to action “Prøv en simulering” (“Try a simulation”) and the address virtualaicorp.no/forhandsvisning are the approved ones.

Weakest The serif typeface loses the crossbar in H and A: the hook reads “I lvem ville du spurt?” and the wordmark “Virtual Λ/ Corp”.

No delivery

Mistral Medium 3.5

not assessed

Mistral AI

Not delivered within the budget (USD 23)

Stopped on 28 September 2026 after 8.5 minutes without a delivery: the model's total budget of USD 23 for the three tasks had been used up.

Other benchmarks

What do international benchmarks say?

Our own tests show how the models solve three concrete tasks. Here is what independent, international benchmarks say about the same models. The figures are measured by others, with other tasks and settings, and have not been checked by us.

International benchmarks of the models we have tested, with the providers' list prices at the end. The highest value among our models is highlighted.

International benchmarks of the models we have tested, with the providers' list prices at the end. The highest value among our models is highlighted.
ModelArena textArena · 02/10/2026Arena codeArena · 02/10/2026Arena agentArena · 02/10/2026ECIEpoch AI · 04/10/2026List priceUSD per 1M tokens, in / out
Claude Opus 5.5Anthropic1,504high · 4,552 votes1,815max · 2,062 votes0.138high · 5,359 sessions167.44 / 20
GPT-6 SolOpenAI1,457max · 8,787 votes1,689max · 3,411 votes0.097max · 6,106 sessionsnot measured2 / 10
Claude Fable 5.1Anthropic1,501max · 11,800 votes1,749max · 6,318 votes0.143max · 15,130 sessions164.810 / 50
Gemini 3.8 FlashGoogle1,495high · 26,298 votes1,583high · 8,524 votes0.030high · 34,396 sessions156.90.75 / 3.75
Gemini 3.1 ProGoogle1,487121,806 votes1,44624,347 votes-0.07786,483 sessions154.82 / 12
Mistral Medium 3.5Mistral AI1,42711,757 votes1,2632,322 votes-0.12411,156 sessions141.41.65 / 8.25

Higher is better in all the benchmarks, and for list prices lower is better. The variant the model was measured with is shown below the figure, because the sources often measure a different reasoning level from the one we use (“high”). Arena scores with few votes are uncertain.

Last updated: Epoch AI 04/10/2026 · Arena 02/10/2026. Sources: Epoch AI (CC BY 4.0, fetched 4 October 2026); Arena (LMArena) (CC BY 4.0, fetched 4 October 2026). Selected and rounded by us.

How to read it

The table shows how the models fare outside our three tasks. Arena is based on user votes, and Epoch AI combines many tests with answer keys into one index.

The benchmarks use other tasks, in English and often at a different reasoning level from ours. Use them alongside our results, not instead of them.

All international benchmarks
Arena text
Users ask the same question to two anonymous models and pick the better answer. The result is a ranking in Arena scores, calculated with the Bradley–Terry model and with style control (answer length and formatting do not count), as Arena itself shows it.
Arena code (WebDev)
As above, but users ask for websites and apps and judge what is built. There is no style-controlled variant here.
Arena agent
Users judge the model as an agent in longer working sessions with tools. Measured in sessions, not votes.
Epoch Capabilities Index (ECI)
Epoch's composite index. It weights many benchmarks by how hard they are, so models can be compared even if they have not taken exactly the same tests.
List price
The provider's own price per million tokens in and out, read from their pricing pages. Not a benchmark.

The models

Who we test, and where data is processed

The models are run through the providers' own APIs. The tests contain only public material and no information about students or users of the tool. The table shows where each provider processes what is sent. More models are added as they are tested.

The models we have tested, with provider, list price and where data is processed
ModelProviderList priceUSD per 1M tokens, in / outWhere data is processed
Claude Fable 5.1Anthropic10 / 50 USA (Anthropic). Requires 30 days of retention by the provider.
Claude Opus 5.5Anthropic4 / 20 USA (Anthropic).
Gemini 3.1 Pro (preview)Google2 / 12 Google (no EU region in the Developer API). Abuse logs kept for 55 days. A paid key is required in the EEA.
Mistral Medium 3.5Mistral AI1.65 / 8.25EU endpoint, 10% more expensiveEU EU (Mistral AI, France), via the EU endpoint.
Claude Sonnet 5.5Anthropic2 / 10 USA (Anthropic).
GPT-6.1 SolOpenAI2 / 10 USA (OpenAI). Abuse logs kept for 30 days. Nothing is stored in the API (store: false).
GPT-6 SolOpenAI2 / 10 USA (OpenAI). Abuse logs kept for 30 days. Nothing is stored in the API (store: false).
Gemini 3.8 FlashGoogle0.75 / 3.75introductory price until 31 Dec 2026 Google (no EU region in the Developer API). Abuse logs kept for 55 days. A paid key is required in the EEA.

Security

How we keep the tests separate

The models get no login and no keys. The calls to the providers and the speech generation are made by our runner outside the model's working environment. The deliveries are shown from the storage service's own address in a restricted frame, not from virtualaicorp.no, so the code the models have written never runs side by side with our login.

  1. The model's containerNo network, no login and no keys.
  2. Our runnerCalls the provider and the speech generation on the model's behalf.
  3. A separate storage addressThe delivery is shown in a restricted frame, not from virtualaicorp.no.

The results apply to version 1.2 of the tasks. Results from different versions are not compared directly.